<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="http://www.javarchitect.com/feed.xml" rel="self" type="application/atom+xml" /><link href="http://www.javarchitect.com/" rel="alternate" type="text/html" /><updated>2026-07-25T21:17:50+00:00</updated><id>http://www.javarchitect.com/feed.xml</id><title type="html">JavaRchitect</title><subtitle>Hi! I&apos;m a Java developer with a passion for software and solution architecture. I love designing clean, scalable systems that solve real problems. Get in touch and let’s see how I can help bring your ideas to life!  </subtitle><author><name>Rodney Taylor</name></author><entry><title type="html">Microservice Communication Styles and Patterns</title><link href="http://www.javarchitect.com/microservice-comm-styles-n-patterns/" rel="alternate" type="text/html" title="Microservice Communication Styles and Patterns" /><published>2026-05-14T00:00:00+00:00</published><updated>2026-05-14T00:00:00+00:00</updated><id>http://www.javarchitect.com/microservice-comm-styles-n-patterns</id><content type="html" xml:base="http://www.javarchitect.com/microservice-comm-styles-n-patterns/"><![CDATA[<p>There are so many different technologies you can use to communicate between microservices. So many that the choices become overwhelming. Should you use a message broker? gRPC? REST over HTTP? The added complexity here is that new communication technologies are being added all the time, making it harder to choose the right way forward.</p>

<h1 id="introduction">Introduction</h1>
<p>Definition of Microservices:</p>
<blockquote>
  <p>A type of service oriented architecture where the services are independently deployable and boundaries are primarily defined by the business domain.</p>
</blockquote>

<p>Keywords from the definition above:</p>
<ul>
  <li>service-oriented architecture =&gt; a set of <strong>collaborating services</strong> which typically run on different computers, with communication between them done via <strong>network-based protocols</strong>.</li>
  <li>independently deployable =&gt; the unit of release (architecture quanta) is a single microservice</li>
  <li>business domain =&gt; the structure of the business domain guides the structure of the architecture. The business domain defines the boundaries between microservices</li>
</ul>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/business_domains_drive_boundaries.png" alt="Business domains drive boundaries of microservices" /></p>

<h1 id="distributed-systems">Distributed Systems</h1>
<p>3 Golden Rules of distributed computing:</p>
<ol>
  <li>You can’t beam information between 2 points instantly</li>
  <li>Sometimes, you can’t reach the point you want to talk to</li>
  <li>Resource pools are NOT infinite: CPU, network utilisation, memory, disk space</li>
</ol>

<h1 id="communication-styles">Communication Styles</h1>
<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/microservices_dependencies.png" alt="Dependencies between microservices" /></p>

<p>2 main communication styles:</p>
<ol>
  <li><strong>Request/Response</strong><br />
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/request_response.png" alt="Request/response communication style" /></li>
  <li><strong>Event-driven</strong><br />
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/event_driven.png" alt="Event-driven communication style" /></li>
</ol>

<table>
  <thead>
    <tr>
      <th>Request/Response</th>
      <th>Event-driven</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>The consumer is <strong>asking</strong> the microservice for something</td>
      <td>The consumer is is <strong>reacting</strong> to an event</td>
    </tr>
    <tr>
      <td>The intent lives with the requesting microservice</td>
      <td>The intent lives with the recipients of the event</td>
    </tr>
    <tr>
      <td>GRPC, REST, CORBA, etc</td>
      <td>Kafka</td>
    </tr>
    <tr>
      <td>✅ Simpler technology <br /> ✅ Familiar flow <br /> ❌ Tighter coupling</td>
      <td>✅ Better in scaling <br /> ✅ Loose coupling <br /> ❌ Complex failure scenarios</td>
    </tr>
  </tbody>
</table>

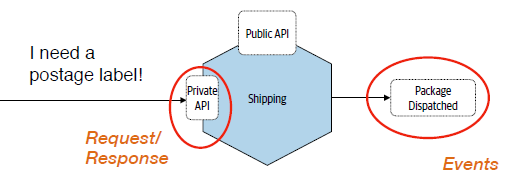
<p>A microservice can expose multiple endpoints with different communication styles. Separation of private and public API endpoints allows for best mix of communication protocols in the system, e.g. REST on public, GRPC &amp; pub/sub on private.
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/multiple_endpoints.png" alt="Multiple endpoints on a microservice" /></p>

<h1 id="defining-boundaries">Defining Boundaries</h1>
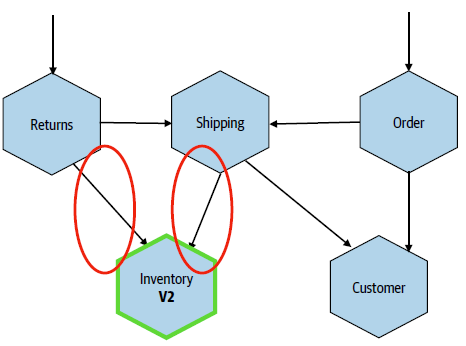
<p><strong>Backwards compatibility</strong> is key in having <strong>independent deployability</strong> in microservices.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/backward_compatibility.png" alt="Backwards compatibility for making sure we don't break upstream consumers" /></p>

<blockquote>
  <p>Anything <strong><em>hidden</em></strong> can change as needed</p>

  <p>Anything <strong><em>exposed</em></strong> becomes part of your service interface</p>
</blockquote>

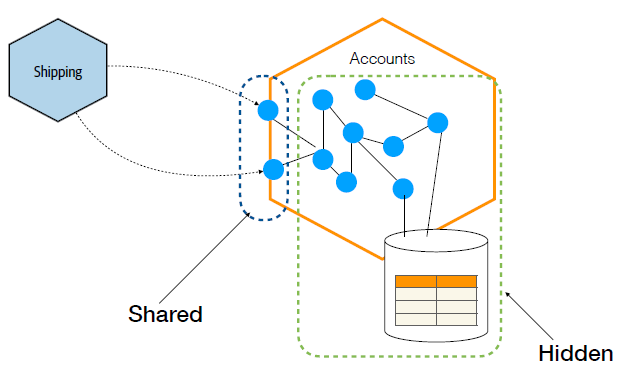
<h2 id="information-hiding">Information Hiding</h2>
<p>Information hiding holds an important role to ensure backward compatibility.</p>

<blockquote>
  <p>Be <strong>explicit</strong> about what is hidden and what is shared</p>

  <p>The <strong>more</strong> you hide: the <strong>easier</strong> it is to maintain <strong><em>backward compatibility</em></strong> and achieve <strong><em>independent deployability</em></strong>.</p>
</blockquote>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/hidden_shared.png" alt="Hidden things can change; shared things can't" /></p>

<h2 id="consumer-first-mindset">Consumer-First Mindset</h2>
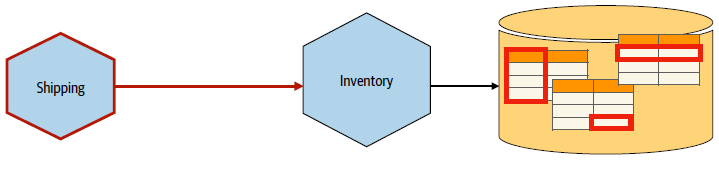
<p>Consumer-first mindset helps us in deciding which information to hide.</p>

<p>This brings us to have an <strong><em>outside-in thinking</em></strong> rather than inside-out thinking. That is, we treat our microservice endpoints like a User Interface (UI):</p>
<ul>
  <li><strong><em>who is going to consume your microservices?</em></strong></li>
  <li><strong><em>what are they trying to achieve?</em></strong></li>
  <li><strong><em>what SLOs (Service Level Objectives) do your clients need?</em></strong></li>
  <li><strong><em>what interface makes their jobs easier?</em></strong></li>
  <li><strong><em>what are their requirements in terms of availability and latency?</em></strong></li>
</ul>

<blockquote>
  <p>Understand your consumers and what they want, design an endpoint that only exposes what they need.</p>
</blockquote>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/minimal_exposure.png" alt="An endpoint that only exposes what consumers need" /></p>

<h2 id="schema-first-design-or-contract-first-design">Schema-First Design (or Contract-First Design)</h2>
<p>Schema-first design provides consumers of your microservices with <strong>explicit schemas</strong>. It opens communication with your customers in <strong><em>understanding what they need</em></strong>.</p>

<p>Common use cases:</p>
<ul>
  <li>GraphQL APIs: Using SDL (Schema Definition Language) to define types.</li>
  <li>REST APIs: Using OpenAPI (Swagger) specifications.</li>
  <li>gRPC APIs: Using Protocol Buffers (.proto files).</li>
</ul>

<h1 id="synchronous-vs-asynchronous">Synchronous vs Asynchronous</h1>
<p>Synchrounous vs Asynchronous communication can mean 2 things:</p>
<ol>
  <li>Blocking vs non-blocking calls</li>
  <li>Temporal de-coupling</li>
</ol>

<h2 id="blocking-vs-non-blocking-calls">Blocking vs Non-blocking Calls</h2>
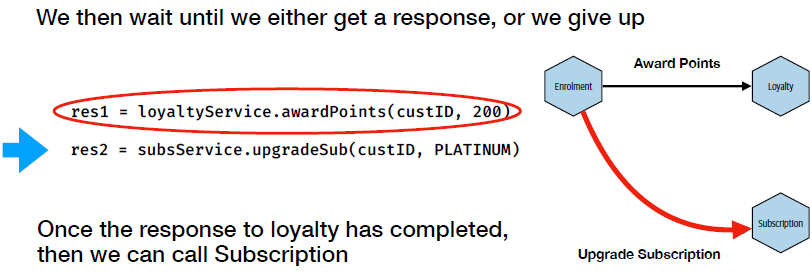
<p>Blocking calls =&gt; when the execution of a program needs to wait for the response from a service. Thus, the latency is the total sum of the calls.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/blocking_calls.png" alt="Blocking calls" /></p>

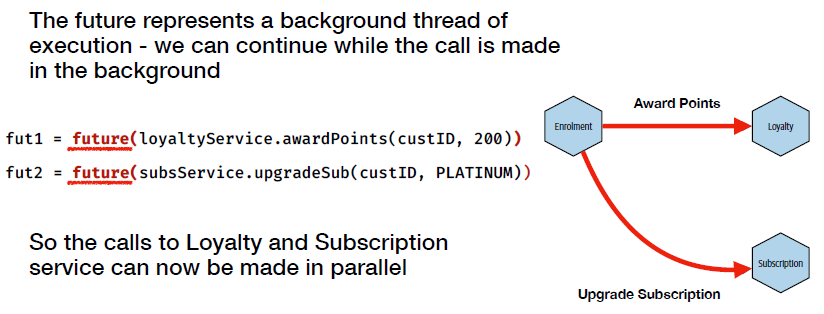
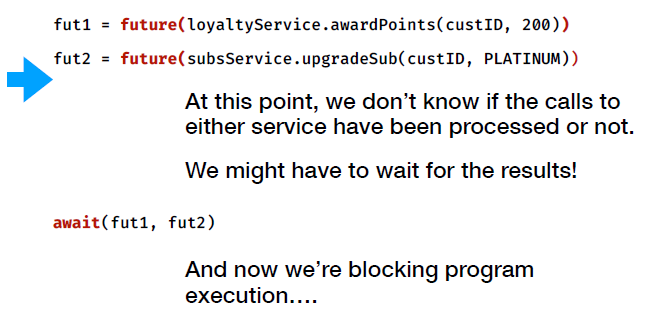
<p>To achieve non-blocking calls, we need to do the calls in <strong>parallel</strong> on separate thread. However, program execution might still need to wait at some point when the response is needed but not yet available.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/non_blocking_calls.png" alt="Non-blocking calls" /></p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/wait_non_blocking_calls.png" alt="Awaiting non-blocking calls" /></p>

<h2 id="temporal-decoupling">Temporal Decoupling</h2>
<p>Temporal coupling =&gt; when <em>two or more processes</em> have to be up and available <strong><em>at the same time</em></strong> for an operation to complete.</p>

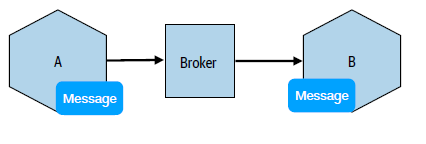
<p>To achieve temporal decoupling, we can use intermediaries such as a <strong>broker</strong>.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/broker.png" alt="Broker" /></p>

<p>It is arguable that the intermediary-based communication encourages stateless processing as a response can be received by a different instance:
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/stateless_processing.png" alt="Stateless processing" /></p>

<h2 id="summary">Summary</h2>

<table>
  <thead>
    <tr>
      <th>Non-blocking Clients</th>
      <th>Temporal Decoupling</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Clients don’t block local thread execution whilst waiting for a remote server</td>
      <td>Remove the need for both client and server to be available at the same time</td>
    </tr>
  </tbody>
</table>

<h1 id="sagas">Sagas</h1>
<p>Saga patterns are considered highly suitable for microservices because they solve one of the biggest problems in distributed systems: <strong><em>How do you maintain business consistency across multiple independent services without using a giant distributed transaction?</em></strong></p>

<p>In a monolith, a single ACID database transaction can coordinate everything.</p>

<p>In microservices, ACID transaction cannot be achieved:</p>
<ul>
  <li>each service owns its own database</li>
  <li>services are independently deployable</li>
  <li>networks are unreliable</li>
  <li>distributed transactions are expensive and fragile</li>
</ul>

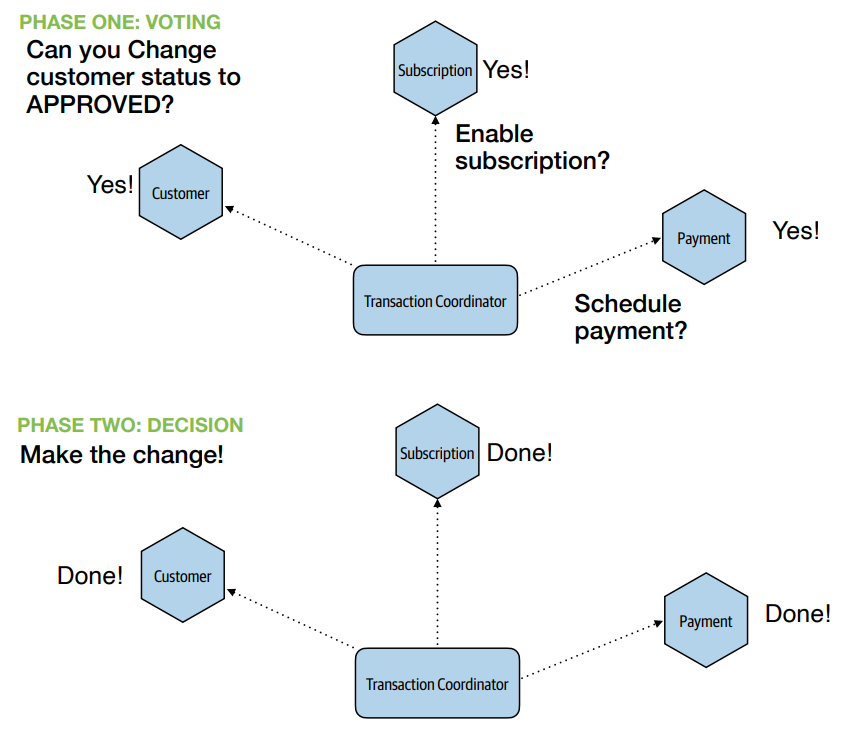
<p>Also, 2-Phase Commit (2PC) causes problems in microservices architecture:</p>
<ul>
  <li>Blocking: services hold locks while waiting to commit</li>
  <li>Poor performance: multiple network round trips and synchronous coordination increase latency</li>
</ul>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/2_phase_commit.png" alt="2-Phase Commit" /></p>

<p>Sagas provide a practical way to coordinate workflows across services while preserving service autonomy:</p>
<ul>
  <li><strong>Orchestration</strong> or <strong>Choreographed</strong> coordination</li>
  <li><strong>Compensating updates</strong> as business-level logic, rather than infrastructure (database) concern, when failure happens</li>
</ul>

<p>See more information <a href="http://www.javarchitect.com/distributed-systems-saga-patterns">here</a></p>

<h1 id="key-technologies">Key Technologies</h1>
<h2 id="api-gateways">API Gateways</h2>
<p>API Gateways act like networking gateway (bridging 2 networks) with additional features around API access.</p>

<p>About API gateways:</p>

<table>
  <thead>
    <tr>
      <th>Good Stuff</th>
      <th>Avoid</th>
      <th>Notes</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Mapping external calls to internal APIs</td>
      <td>Network security for inter-microservice comms</td>
      <td>Use a service mesh instead</td>
    </tr>
    <tr>
      <td>API key management</td>
      <td>Protocol rewriting</td>
      <td>Do this in the microservice</td>
    </tr>
    <tr>
      <td>Rate limiting</td>
      <td>Call aggregation &amp; filtering</td>
      <td>Consider GraphQL or BFF (Backend for Frontend) instead</td>
    </tr>
    <tr>
      <td>Developer Portals</td>
      <td> </td>
      <td> </td>
    </tr>
  </tbody>
</table>

<blockquote>
  <p>API Gateways are a vendor product - you don’t want your core system smarts in there</p>

  <p>“Keep your endpoints smart, and your pipes dumb”</p>

  <p>Treat API gateways like a dumb pipe!</p>
</blockquote>

<h2 id="service-meshes">Service Meshes</h2>
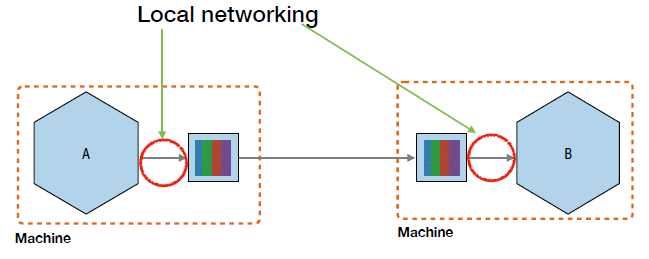
<p>A <strong>service mesh</strong> is an infrastructure layer that manages communication between microservices.<br />
Instead of implementing networking concerns inside each service, these concerns are delegated to lightweight network proxies (sidecars) managed by the mesh.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/service_mesh.png" alt="Service Mesh" /></p>

<p>Traditional microservices often duplicate networking logic such as:</p>
<ul>
  <li>retries</li>
  <li>timeouts</li>
  <li>TLS</li>
  <li>load balancing</li>
  <li>circuit breaking</li>
  <li>metrics</li>
  <li>tracing</li>
</ul>

<p>A service mesh centralizes these concerns.</p>

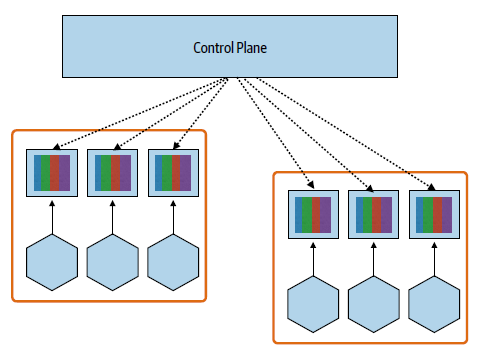
<p>Mutual TLS is mostly useful on Kubernetes when using service mesh. A control plane is used to manage sidecars spread around the system, e.g. certificate distribution, etc.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/service_mesh_control_plane.png" alt="Control place in service mesh" /></p>

<p>When to use:</p>
<ul>
  <li>Hugely beneficial for mutual TLS on Kubernetes</li>
  <li>Especially useful for platform teams, and in polyglot environments</li>
  <li>Can be a requirement for other tech (e.g. KNative)</li>
</ul>

<h2 id="message-brokers">Message Brokers</h2>
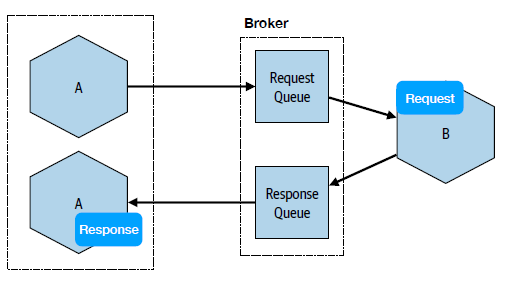
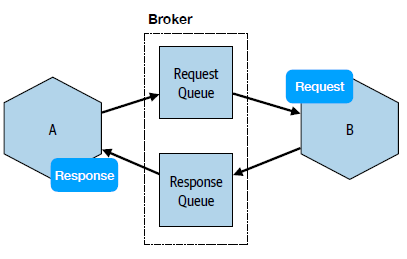
<p>In request/response communication, message brokers allows offloading workload with guaranteed delivery:
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/brokers_request_response.png" alt="Message brokers for request/response communication" /></p>

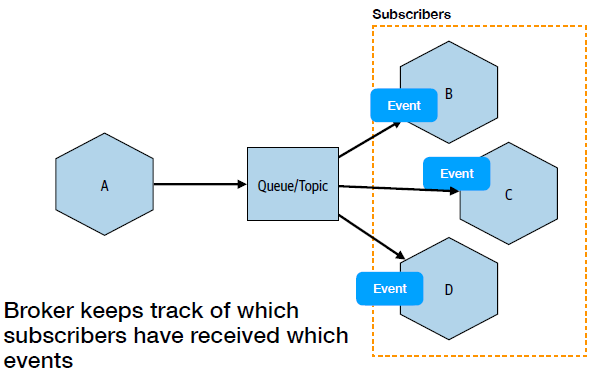
<p>In event-driven communication, message brokers keep tracks of which subscribers have received which events:
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/brokers_event_driven.png" alt="Message brokers for event-driven communication" /></p>

<p>When to use message brokers:</p>
<ul>
  <li>Reduce/eliminate temporal coupling with your own services</li>
  <li>Offload some of the work for guaranteed delivery</li>
  <li>Especially useful for event-driven interactions</li>
</ul>

<h1 id="retries-timeouts-and-latency">Retries, Timeouts and Latency</h1>
<h2 id="timeouts">Timeouts</h2>
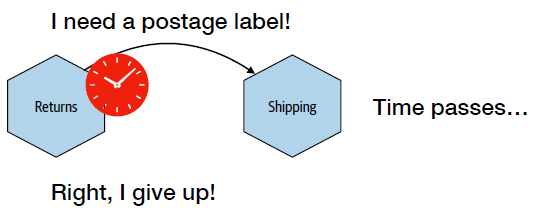
<p>Timeouts =&gt; a threshold after which a request will be terminated if not completed.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/timeout.png" alt="Timeout" /></p>

<p>Why timeout:</p>
<ul>
  <li>resources: the longer you wait, the more resources are used</li>
  <li>recovery: if something is going to fail, you want to fail fast</li>
</ul>

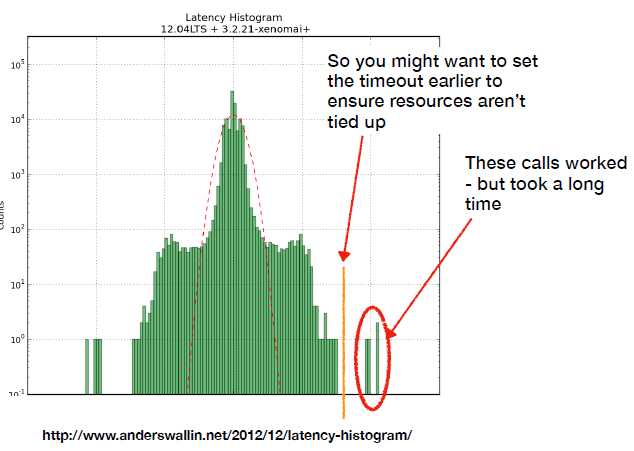
<p>Timeout management:</p>
<ol>
  <li>Understand normal system performance to determine timeout value, e.g. latency distribution chart within your observability tools</li>
  <li>Error on the side of caution</li>
  <li>Ensure you can change timeout <strong>independent</strong> of software releases</li>
  <li>Keep observing!</li>
</ol>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/timeout_system_performance.png" alt="System performance for determining timeout value" /></p>

<h2 id="retries">Retries</h2>
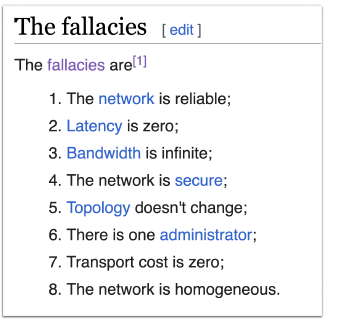
<p>#1 in the fallacies of distributed computing is that the network is NOT 100% reliable.</p>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/fallacies_of_distributed_computing.png" alt="The Fallacies of Distributed Computing" /></p>

<h3 id="idempotency-operations">Idempotency Operations</h3>
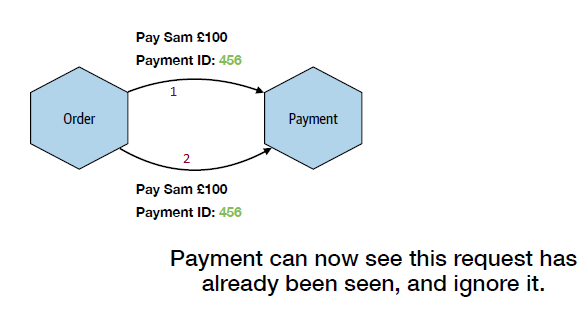
<p>=&gt; an operation that can be applied <em>multiple</em> times <strong>WITHOUT</strong> changing the result.</p>

<p>Idempotency operations allows multiple retries as a safe mechanism to deal with timeouts or unreliable network.</p>

<p>For example, this can be achieved by specifying an operation ID in the request.
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/payment_id.png" alt="Idempotency operation using payment ID" /></p>

<h2 id="latency">Latency</h2>
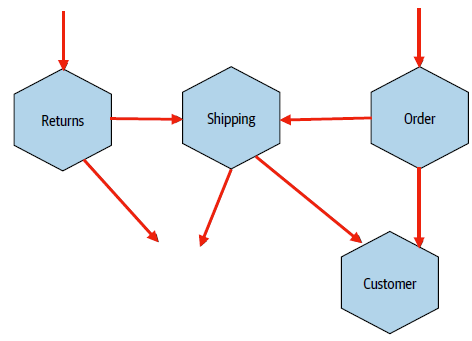
<p>Microservices architecture suffers in latency due to lots of network hops. 
<img src="../assets/images/posts/microservice_comm_styles_n_patterns/network_hops.png" alt="Network hops bring latency up" /></p>

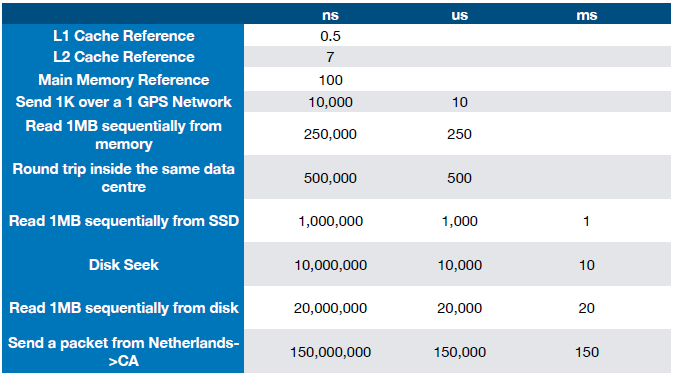
<p>How to improve latency in microservices architecture:</p>
<ul>
  <li>Be aware of what takes time</li>
  <li>Don’t hide the network (latency) in architecture diagrams</li>
  <li>Run operations in parallel</li>
  <li>Don’t make calls</li>
  <li>Use different technology</li>
  <li>Merge things back together</li>
</ul>

<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/latency_cost.png" alt="Typical latency cost" /></p>

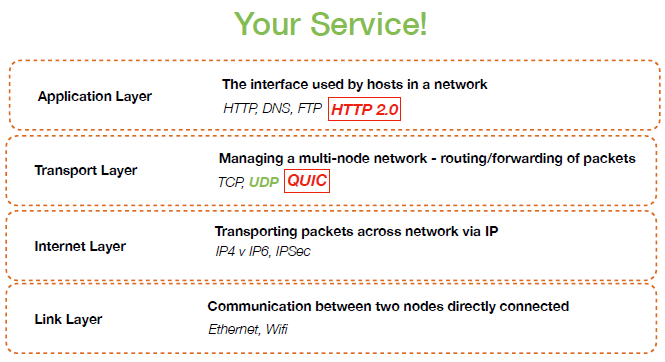
<p><img src="../assets/images/posts/microservice_comm_styles_n_patterns/internet_protocol_suite.png" alt="Use different technologies for better latency" /></p>

<h1 id="technology-links">Technology Links</h1>
<ul>
  <li><a href="https://protobuf.dev/">Protobuf is 5-6 times faster than JSON</a></li>
  <li><a href="https://github.com/aeron-io/simple-binary-encoding">Simple Binary Encoding (SBE) is more efficient than Protobuf</a></li>
  <li><a href="https://linkerd.io/">Linkerd</a></li>
  <li><a href="https://istio.io/">Istio</a></li>
  <li><a href="https://temporal.io/">Temporal</a></li>
  <li><a href="https://specmatic.io/">Specmatic</a></li>
  <li><a href="https://docs.confluent.io/current/schema-registry/index.html">Confluent - schema management</a></li>
  <li><a href="https://github.com/OpenAPITools/openapi-dif">OpenAPI-diff</a></li>
  <li><a href="https://www.slideshare.net/slideshow/http3-129039527/129039527">HTTP/3 = HTTP/2 over QUIC</a></li>
  <li><a href="https://www.google.com/url?sa=t&amp;rct=j&amp;q=&amp;esrc=s&amp;source=web&amp;cd=&amp;cad=rja&amp;uact=8&amp;ved=2ahUKEwiQkrv79riUAxVGQUEAHUOrHGAQwqsBegQIaRAB&amp;url=https%3A%2F%2Fwww.youtube.com%2Fwatch%3Fv%3DsULCOKfc87Y&amp;usg=AOvVaw0-TfGhBKectSmQC2KsJ6DL&amp;opi=89978449">QUIC</a></li>
</ul>

<h1 id="resource">Resource</h1>
<ul>
  <li><em>Microservices Comms Styles and Patterns: Microservice Collaboration</em> - Live Event by Sam Newman</li>
  <li><a href="https://www.oreilly.com/library/view/building-microservices-2nd/9781492034018/">Building Microservices by Sam Newman</a></li>
</ul>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[There are so many different technologies you can use to communicate between microservices. So many that the choices become overwhelming. Should you use a message broker? gRPC? REST over HTTP? The added complexity here is that new communication technologies are being added all the time, making it harder to choose the right way forward.]]></summary></entry><entry><title type="html">Architecture Patterns and Anti-Patterns</title><link href="http://www.javarchitect.com/architecture-patterns-and-antipatterns/" rel="alternate" type="text/html" title="Architecture Patterns and Anti-Patterns" /><published>2026-05-03T00:00:00+00:00</published><updated>2026-05-03T00:00:00+00:00</updated><id>http://www.javarchitect.com/architecture-patterns-and-antipatterns</id><content type="html" xml:base="http://www.javarchitect.com/architecture-patterns-and-antipatterns/"><![CDATA[<p>I have a new software project. As a solution architect, where should I start?</p>

<h1 id="expected-outcomes">Expected Outcomes</h1>

<p>[ ] Differentiate between an architectural style and a pattern, and understand how they fit together in software architecture
[ ] Identify patterns that you can use to tackle common architecture problems
[ ] Discover antipatterns to avoid in software architecture
[ ] Determine the proper communcation style to derive the most benefit from a particular architecture pattern</p>

<p>We will learn:
[ ] Key architectural patterns used within modern software architectures
[ ] The strengths and trade-offs associated with each pattern
[ ] Antipatterns to avoid when architecting software</p>

<h1 id="introduction">Introduction</h1>
<p>An architectural pattern, much like a design pattern, is a reusable solution to problems an architect commonly encounters when designing systems. Exposure to architecture patterns, and knowing how to leverage them appropriately, are critical foundational skills for all architects.</p>

<p>Gaining a solid understanding of architectural patterns and a valuable toolkit to enhance your capability as a software architect is fundamental. Also is the case with knowing the differences between architectural styles (such as layered and microservices) and architectural patterns (such as messaging and caching patterns). With that foundation, we’ll delve into a variety of architectural patterns, their ideal applications, and the trade-offs each pattern presents. We’ll also explore emerging patterns and antipatterns in AI.</p>

<h1 id="definitions">Definitions</h1>
<p>Architecture pattern = contextualised solution to an architectural problem.</p>

<p>Architecture patterns affects topology and capabilities of the solution.</p>

<p>Anti-pattern = a solution that looks like a pattern but turns out to do more damage than benefit.</p>

<h1 id="architecture-patterns">Architecture Patterns</h1>

<h2 id="workflow-patterns">Workflow Patterns</h2>

<h3 id="orchestration">Orchestration</h3>

<h4 id="ideal-applications">Ideal Applications</h4>

<h4 id="trade-offs">Trade-offs</h4>

<h3 id="choreography">Choreography</h3>

<h4 id="ideal-applications-1">Ideal Applications</h4>

<h4 id="trade-offs-1">Trade-offs</h4>

<h3 id="hybrid">Hybrid</h3>

<h4 id="ideal-applications-2">Ideal Applications</h4>

<h4 id="trade-offs-2">Trade-offs</h4>

<h2 id="broker-patterns">Broker Patterns</h2>

<h3 id="domain-broker-pattern">Domain Broker Pattern</h3>

<h4 id="ideal-applications-3">Ideal Applications</h4>

<h4 id="trade-offs-3">Trade-offs</h4>

<h3 id="multi-broker-pattern">Multi-Broker Pattern</h3>

<h4 id="ideal-applications-4">Ideal Applications</h4>

<h4 id="trade-offs-4">Trade-offs</h4>

<h2 id="event-contract-patterns">Event Contract Patterns</h2>

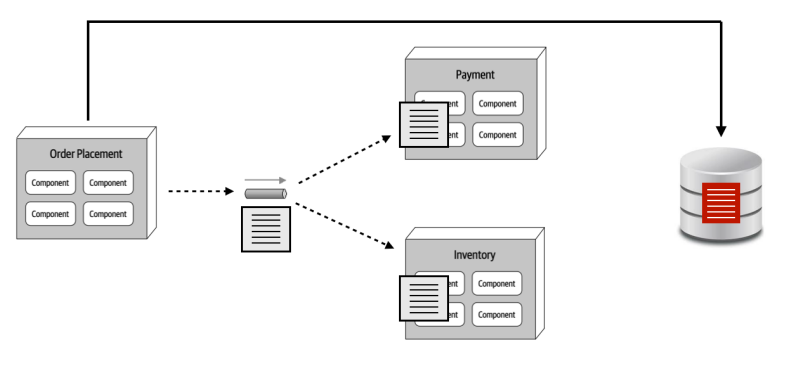
<h3 id="data-based-contract-pattern">Data-based Contract Pattern</h3>

<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/data_based_contract_pattern.png" alt="Data-based Contract Pattern" /></p>

<p>Characteristics:</p>
<ul>
  <li>We transfer hydrated contract to each service</li>
</ul>

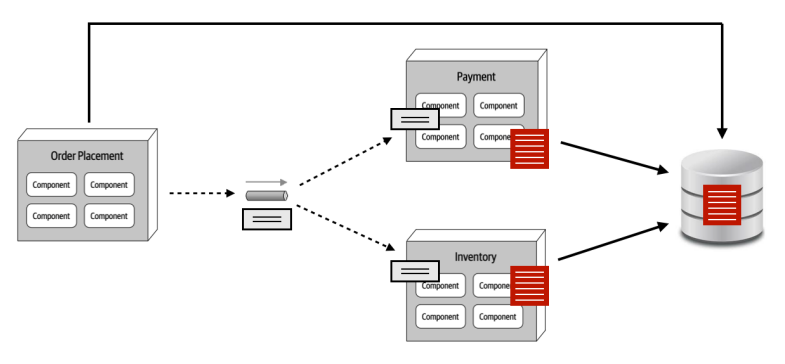
<h3 id="key-based-contract-pattern">Key-based Contract Pattern</h3>

<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/key_based_contract_pattern.png" alt="Key-based Contract Pattern" /></p>

<p>Characteristics:</p>
<ul>
  <li>We only transfer the values each service needs</li>
  <li>We touch the DB a lot</li>
</ul>

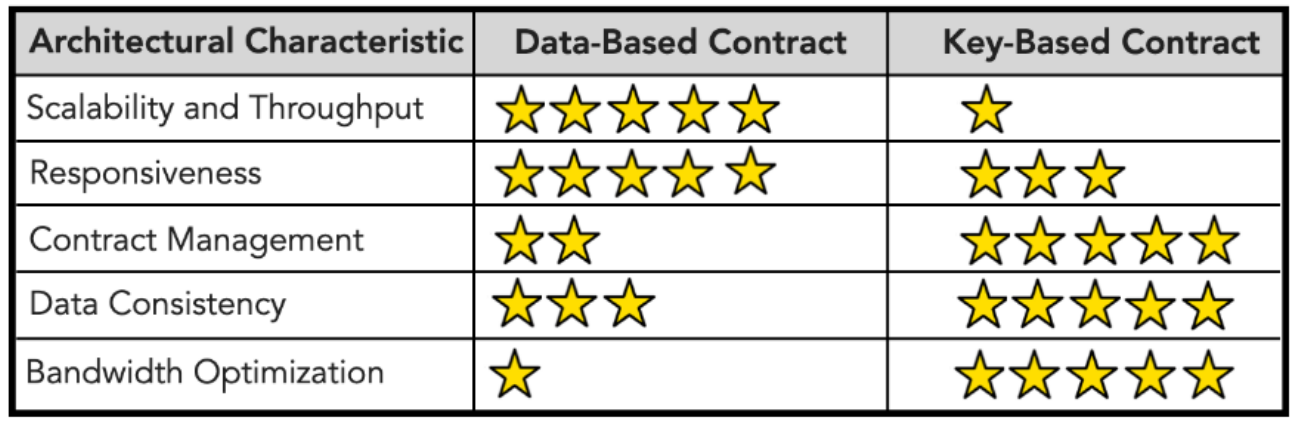
<h3 id="comparison">Comparison</h3>

<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/contract_patterns_comparison.png" alt="Data-based vs Key-based Contract patterns" /></p>

<h2 id="anti-patterns">Anti-Patterns</h2>

<h3 id="grain-of-sand-anti-pattern">Grain-of-Sand Anti-pattern</h3>

<p>How small should your microservices be?</p>

<h3 id="swarm-of-gnats-anti-pattern">Swarm-of-Gnats Anti-pattern</h3>

<p>=&gt; Triggering multitude events based on multiple state changes or actions.</p>

<p>The higher granularity a system has:</p>
<ul>
  <li>The more fault tolerant the system is</li>
  <li>The lower the performance is due to multiple inter-service communication</li>
</ul>

<p>There are some disintegrators and integrator that can be used to help break down and consolidate services. More information can be found here: <link to="" previous="" confluence="" doc="" /></p>

<p>Consolidating several services into 1 can be a good answer to avoid swarm-of-gnats anti-pattern. Indication of this is when an event triggers all the relevant services, or none of the relevant services.</p>

<h2 id="data-ownership-patterns">Data Ownership Patterns</h2>

<blockquote>
  <p>Owner of a table is whoever writes to the table.</p>
</blockquote>

<p>3 kinds of ownership:</p>
<ol>
  <li>Single</li>
  <li>Joint</li>
  <li>Common</li>
</ol>

<h3 id="single">Single</h3>
<p>1 owner =&gt; the service can be a microservice (highest data fidelity)</p>

<h3 id="joint">Joint</h3>
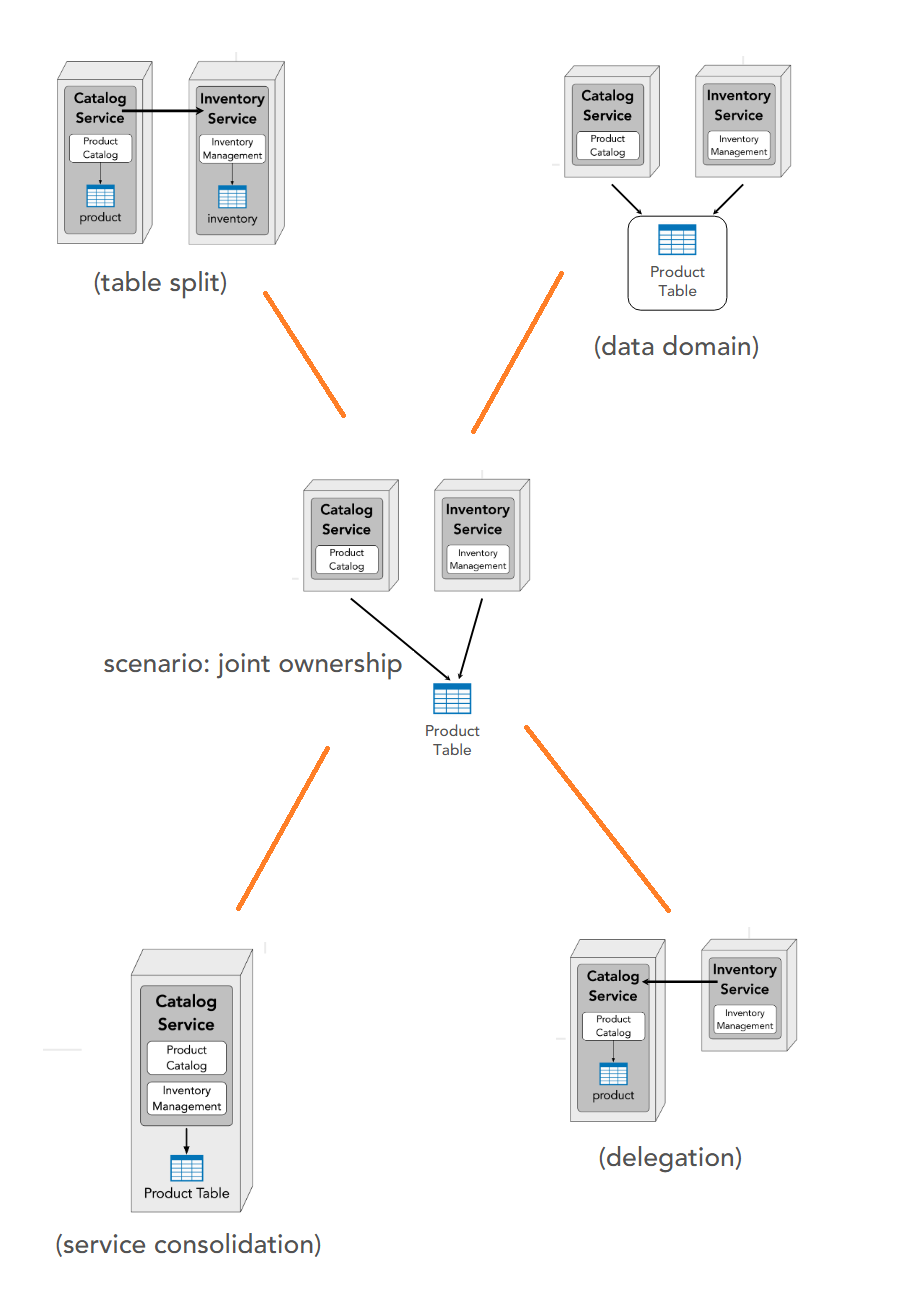
<p>2 owners =&gt; options:
a. Table split: clear separation and services can become microservices. A communication channel between the 2 services is needed.
b. Data domain: table become individual domain
c. Delegation: one service takes ownership and the other communicates with it
d. Consolidation: integrating 2 services into 1 microservice
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/joint_ownership.png" alt="Joint ownership scenario" /></p>

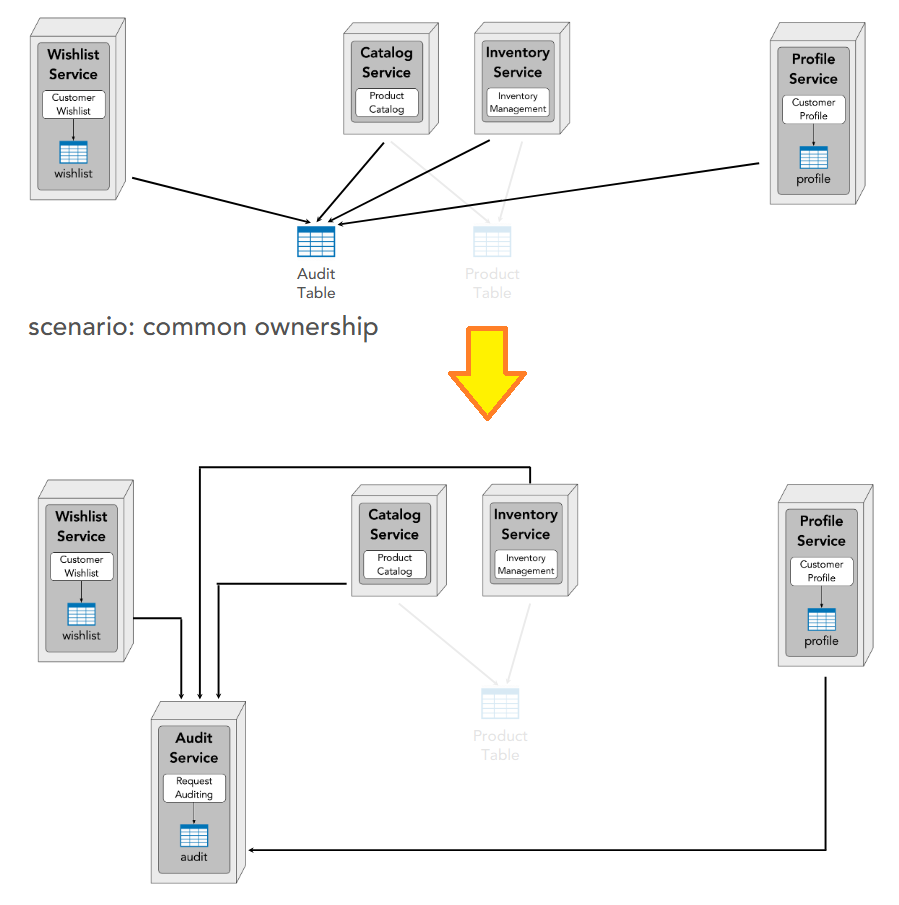
<h3 id="common">Common</h3>
<blockquote>
  <p>2 owners =&gt; create a (proxy) service to be the owner
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/common_ownership.png" alt="Common ownership scenario" /></p>
</blockquote>

<p>Data transfer (i.e. read data I don’t own):</p>
<ol>
  <li>Interservice communication</li>
  <li>Data replication</li>
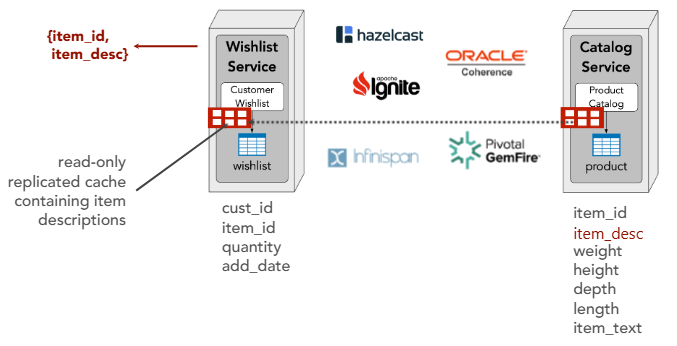
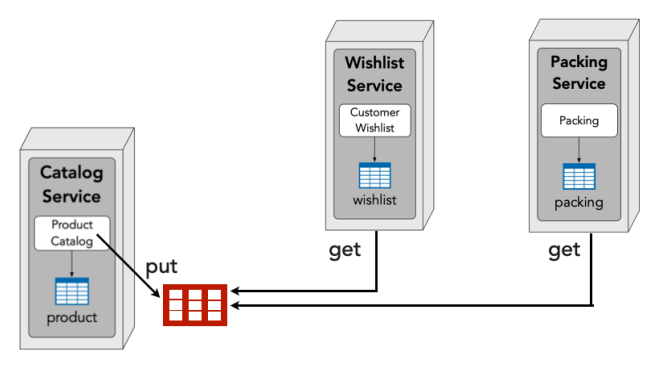
  <li>In-Memory Replicated Cache</li>
  <li>Sidecar Distributed Cache</li>
  <li>Data Domain</li>
</ol>

<h3 id="interservice-communication">Interservice communication</h3>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/inter_service_comms.png" alt="Inter-service communication" /></p>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ go-to solution <br /> ✅ easy to understand and implement</td>
      <td>❌ network, security, and data latency <br /> ❌ scalability and throughput <br /> ❌ fault tolerance</td>
    </tr>
  </tbody>
</table>

<h3 id="data-replication">Data replication</h3>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/data_replication.png" alt="Data replication" /></p>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ network, security, and data latency <br /> ✅ scalability and throughput <br /> ✅ fault tolerance</td>
      <td>❌ data consistency issues <br /> ❌ custom data synchronization <br /> ❌ data ownership issues</td>
    </tr>
  </tbody>
</table>

<h3 id="in-memory-cache">In-Memory Cache</h3>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/in_memory_replicated_cache.png" alt="In-memory replication cache" /></p>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ network, security, and data latency <br /> ✅ scalability and throughput <br /> ✅ fault tolerance <br /> ✅ no data consistency issues <br /> ✅ no custom data synchronization <br /> ✅ no data ownership issues</td>
      <td>❌ data volume issues <br /> ❌ data update rate issues <br /> ❌ eventually consistent <br /> ❌ cold start dependency</td>
    </tr>
  </tbody>
</table>

<h3 id="sidecar-distributed-cache">Sidecar Distributed Cache</h3>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/side_car.png" alt="Side car" /></p>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ network, security, and data latency <br /> ✅ scalability and throughput <br /> ✅ fault tolerance <br /> ✅ no data consistency issues <br /> ✅ no custom data synchronization <br /> ✅ no data ownership issues <br /> ✅ no data volume issues <br /> ✅ no data update rate issues</td>
      <td>❌ cold start dependency <br /> ❌ fault tolerance dependency</td>
    </tr>
  </tbody>
</table>

<h3 id="data-domain-shared-tables">Data Domain (Shared Tables)</h3>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/data_domain.png" alt="Data domain" /></p>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ network, security, and data latency <br /> ✅ scalability and throughput <br /> ✅ fault tolerance <br /> ✅ no data consistency issues <br /> ✅ no custom data synchronization <br /> ✅ no data ownership issues <br /> ✅ no data volume issues <br /> ✅ no data update rate issues <br /> ✅ no cold start dependency</td>
      <td>❌ change control <br /> ❌ data ownership <br /> ❌ possible security issues <br /> ❌ forces the same DBMS for all data</td>
    </tr>
  </tbody>
</table>

<h3 id="use-case">Use Case</h3>
<p>| Option | Best For |
|——–|———-|
| <strong>Interservice communication</strong> | ✅ large data volume <br /> ✅ low responsiveness |
| <strong>Data schema replication</strong> | ✅ reporting <br /> ✅ data aggregation |
| <strong>In-memory replicated cache</strong> | ✅ low data volume <br /> ✅ high responsiveness |
| <strong>Data sidecar distributed cache</strong> | ✅ large data volume <br /> ✅ high responsiveness |
| <strong>Data domains (shared tables)</strong> | ✅ high responsiveness <br /> ✅ data dependencies |</p>

<h3 id="summary-of-data-ownership-patterns">Summary of Data Ownership Patterns</h3>

<table>
  <thead>
    <tr>
      <th>Criteria</th>
      <th style="text-align: center">Interservice Comm.</th>
      <th style="text-align: center">Data Replication</th>
      <th style="text-align: center">In-Memory Cache</th>
      <th style="text-align: center">Sidecar + Dist. Cache</th>
      <th style="text-align: center">Data Domain</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Performance &amp; Reliability</strong></td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
    </tr>
    <tr>
      <td>Network, security &amp; data latency</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>Scalability and throughput</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>Fault tolerance</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td><strong>Data Management</strong></td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
    </tr>
    <tr>
      <td>Data consistency</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>No custom data synchronization</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>Data ownership</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">❌</td>
    </tr>
    <tr>
      <td>Data volume</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>Data update rate</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>No cold start dependency</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">✅</td>
    </tr>
    <tr>
      <td>Eventually consistent</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
    </tr>
    <tr>
      <td><strong>Implementation</strong></td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
      <td style="text-align: center"> </td>
    </tr>
    <tr>
      <td>Easy to understand &amp; implement</td>
      <td style="text-align: center">✅</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
    </tr>
    <tr>
      <td>No change control concerns</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
    </tr>
    <tr>
      <td>No security concerns</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
    </tr>
    <tr>
      <td>No fault tolerance dependency</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
      <td style="text-align: center">—</td>
    </tr>
    <tr>
      <td>DBMS flexibility</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">—</td>
      <td style="text-align: center">❌</td>
    </tr>
  </tbody>
</table>

<h2 id="caching-patterns">Caching Patterns</h2>
<p>Caching topologies:</p>
<ol>
  <li>Single in-memory cache</li>
  <li>Distributed (client/server) cache</li>
  <li>Replicated (in-process) cache</li>
  <li>Near-cache hybrid</li>
</ol>

<h3 id="cache-aside">Cache-aside</h3>
<blockquote>
  <p>The application is the orchestrator for both read and write processes, i.e. the application is aware of both cache and datastore and which operation goes to where.</p>
</blockquote>

<p>Read:</p>
<ul>
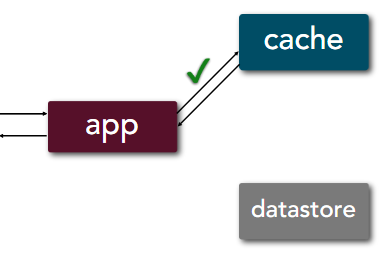
  <li>When data available in cache, it takes 4 steps
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/cache_aside_read_from_cache.png" alt="Cache aside - read from cache: 4 steps" /></li>
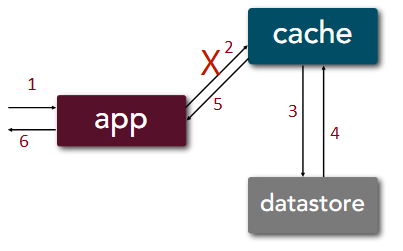
  <li>In the event of a cache-miss, it takes 6 steps. This involves lazy-loading the cache with the missing data.
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/cache_aside_read_from_db.png" alt="Cache-miss: 6 steps" /></li>
</ul>

<p>Write: takes 4 steps
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/cache_aside_write.png" alt="Cache aside - write: 4 steps" /></p>

<p>Use case:</p>
<ul>
  <li>read-heavy loads</li>
  <li>content delivery systems</li>
  <li>reporting systems</li>
</ul>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ <strong>Smaller cache size</strong> because only requested data is cached <br /> ✅ <strong>Flexible implementation</strong> because app manages what gets cached</td>
      <td>❌ <strong>Higher latency</strong> for data that sees a cache miss <br /> ❌ <strong>Higher load</strong> on database depending on read patterns</td>
    </tr>
  </tbody>
</table>

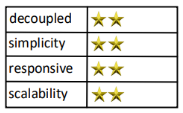
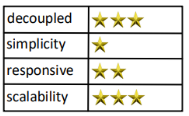
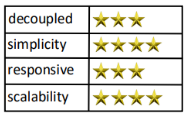
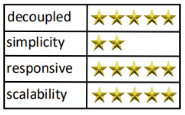
<p>Star rating:
| Capability | With Pattern | Without Pattern |
|—|:—:|:—:|
| <strong>Flexibility</strong> | ★★★★★ | ★★★ |
| <strong>Scalability</strong> | ★★★★ | ★★ |
| <strong>Read Throughput</strong> | ★★★★★ | ★★ |
| <strong>Write Throughput</strong> | ★★★★ | ★★★★★ |
| <strong>Cost</strong> | ★★★★ | ★★★★★ |
| <strong>Responsiveness</strong> | ★★★★ | ★★ |
| <strong>Consistency</strong> | ★★ | ★★★★★ |
| <strong>Simplicity</strong> | ★★★ | ★★ |</p>

<p>Influences in caching topologies:
| Capability | Single In-Memory Cache | Client-Server Cache (Remote) | Replicated In-Memory Cache |
|—|:—:|:—:|:—:|
| <strong>Flexibility</strong> | ★★★★★ | ★★★★ | ★★★★ |
| <strong>Scalability</strong> | ★★ | ★★★★ | ★★★★★ |
| <strong>Read Throughput</strong> | ★★★★★ | ★★★ | ★★★★★ |
| <strong>Write Throughput</strong> | ★★★★ | ★★★ | ★★★ |
| <strong>Cost</strong> | ★★ | ★★★★ | ★ |
| <strong>Consistency</strong> | ★★ | ★★★★ | ★★★ |
| <strong>Simplicity</strong> | ★★★ | ★★★ | ★ |
| <strong>Responsiveness</strong> | ★★★ | ★★ | ★★★★ |</p>

<h3 id="write-around">Write Around</h3>
<p>Read:
same as cache-aside</p>

<p>Write: takes 5 steps
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/write_around__write.png" alt="Write Around - write: 5 steps" />
?? Write-around skips writing to the cache altogehter??? Or, delete the relevant data?</p>

<p>Use case:</p>
<ul>
  <li>write-heavy systems</li>
</ul>

<h3 id="readwrite-through">Read/Write Through</h3>
<blockquote>
  <p>The cache is the orchestrator for both read and write processes, i.e. as far as the application concerns, the cache <strong>is</strong> the only touch-point for data.</p>
</blockquote>

<p>Read:</p>
<ul>
  <li>When data available in cache, it takes 4 steps just like cache-aside
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/read_through_read_from_cache.png" alt="Read-Through - read from cache: 4 steps" /></li>
  <li>In the event of a cache-miss, it takes 6 steps just like cache-aside but via cache
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/read_through_read_from_db.png" alt="Read-Through - cache-miss: 6 steps" /></li>
</ul>

<p>Write: takes 4 steps
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/read_through_write.png" alt="Read-Through - write: 4 steps" /></p>

<p>Use case:</p>
<ul>
  <li>high consistency</li>
  <li>critical applications</li>
  <li>read-heavy systems</li>
</ul>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ <strong>High data consistency</strong> because cache and datastore are in sync <br /> ✅ <strong>Simplified app implementation</strong> because read/write paths are symmetric <br /> ✅ <strong>Fast reads</strong> because cache mirrors datastore</td>
      <td>❌ <strong>Higher latency</strong> for writes <br /> ❌ <strong>Specialized cache</strong> implementation <br /> ❌ <strong>Larger cache size</strong> because all data is cached</td>
    </tr>
  </tbody>
</table>

<p>Star rating:
| Capability | Using Read-Through/Write-Through | Without the Pattern |
|—|:—:|:—:|
| <strong>Consistency</strong> | ★★★★ | ★★★★★ |
| <strong>Responsiveness (Reads)</strong> | ★★★★ | ★★ |
| <strong>Read Throughput</strong> | ★★★★ | ★★ |
| <strong>Simplicity</strong> | ★★★★ | ★★ |
| <strong>Scalability</strong> | ★★★ | ★★ |
| <strong>Flexibility</strong> | ★★ | ★★★ |
| <strong>Cost</strong> | ★★ | ★★★ |
| <strong>Write Throughput</strong> | ★★ | ★★★ |
| <strong>Responsiveness (Writes)</strong> | ★★ | ★★★ |</p>

<p>Influences in caching topologies:
| Capability | In-Memory | Client-Server | Replicated In-Memory |
|—|:—:|:—:|:—:|
| <strong>Consistency</strong> | ★★ | ★★★★ | ★★★ |
| <strong>Responsiveness</strong> | ★★★★ | ★★★ | ★★★★ |
| <strong>Read Throughput</strong> | ★★★★★ | ★★★ | ★★★★★ |
| <strong>Write Throughput</strong> | ★★ | ★★ | ★★★ |
| <strong>Scalability</strong> | ★★ | ★★★★ | ★★★★★ |
| <strong>Simplicity</strong> | ★★★ | ★★★★ | ★★ |
| <strong>Flexibility</strong> | ★★★ | ★★ | ★★★ |
| <strong>Cost</strong> | ★★ | ★★★ | ★★ |</p>

<table>
  <thead>
    <tr>
      <th>Governance</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ <strong>Cache sits</strong> between app and datastore <br /> ✅ Define <strong>SLIs (Service Level Indicator) and SLOs (Service Level Objective)</strong> for cache since they affect the entire architecture <br /> ✅ <strong>Chaos Engineering</strong> to simulate latency and cache failure to assess architectural impact and resiliency</td>
    </tr>
  </tbody>
</table>

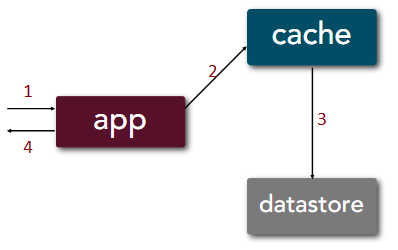
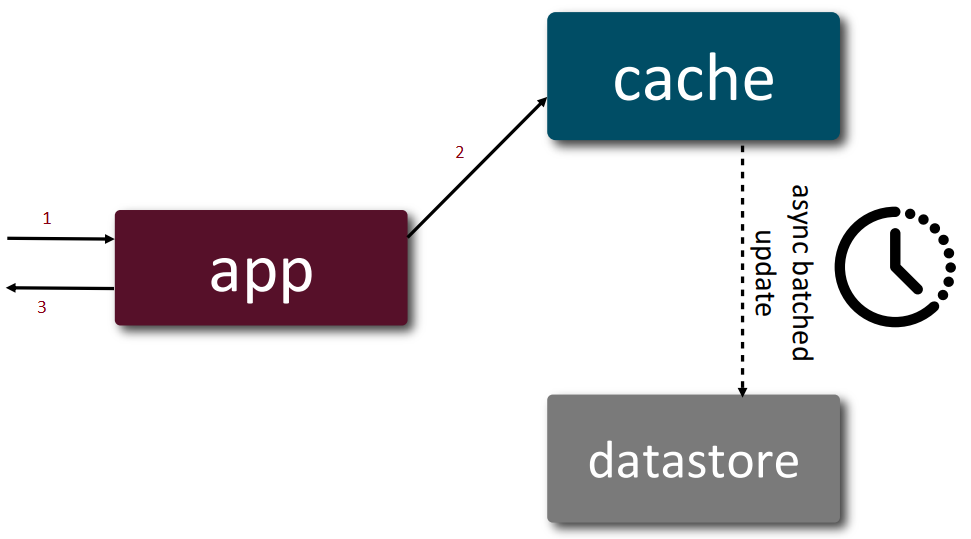
<h3 id="write-behind">Write Behind</h3>
<p>Write: takes 3 steps + async write
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/write_behind.png" alt="Write behind async write" /></p>

<p>Use case:</p>
<ul>
  <li>batch-processing applications</li>
  <li>write-heavy systems</li>
</ul>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ <strong>Low latency for writes</strong> because only cache needs updated <br /> ✅ <strong>Low database load</strong> because writes are batched <br /> ✅ <strong>Fast reads</strong> because cache mirrors datastore</td>
      <td>❌ <strong>Single-point of failure</strong> if cache fails <br /> ❌ <strong>Eventually consistent system</strong> because all datastore updates are batched <br /> ❌ <strong>Larger cache size</strong> because all data is cached</td>
    </tr>
  </tbody>
</table>

<h3 id="prompt-caching">Prompt caching</h3>
<p>With LLM, each time a user send a message, user prompt and system prompt are sent.  However, system prompt don’t change. Hence, the system prompt is cache in the first instance. The 2nd time the user sends a message, the system will take the system prompt from cache and send both the system prompt and user prompt to LLM.</p>

<p>Use case:</p>
<ul>
  <li>large system prompts</li>
</ul>

<table>
  <thead>
    <tr>
      <th>Pros</th>
      <th>Cons</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>✅ less computational cost especially for large system prompts <br /> ✅ better resource utilization because prompts are preprocessed</td>
      <td>❌ complex invocation pattern due to establishing breakpoints <br /> ❌ llm specific since only some offerings support it</td>
    </tr>
  </tbody>
</table>

<h3 id="summary-of-caching-patterns">Summary of Caching Patterns</h3>

<h2 id="continuous-delivery--devops-patterns">Continuous Delivery / DevOps Patterns</h2>

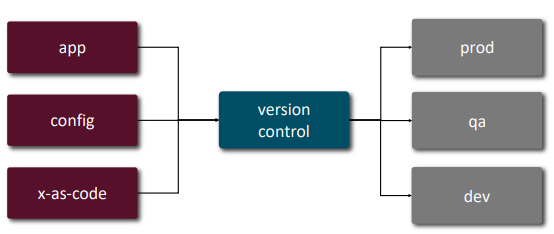
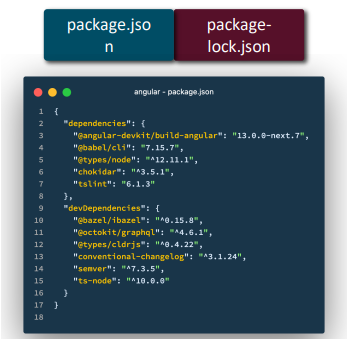
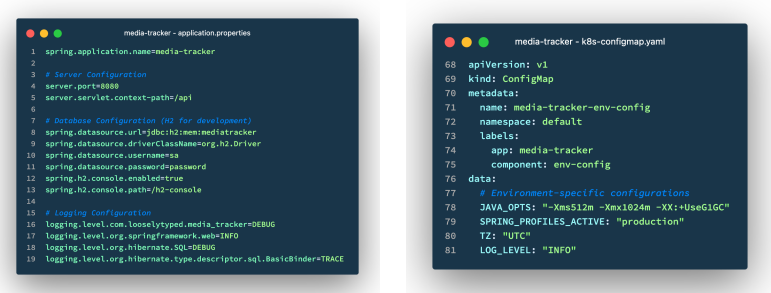
<h3 id="1215-factor-app-principles">12/15 Factor App principles</h3>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Principle</th>
      <th>Summary</th>
      <th>Diagram</th>
      <th> </th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>1</td>
      <td><strong>Codebase</strong></td>
      <td>One codebase tracked in version control, many deploys</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/all_code_in_version_control.png" alt="All code in version control" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>2</td>
      <td><strong>Dependencies</strong></td>
      <td>Explicitly declare and isolate dependencies</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/explicitely_declared_n_isolated_dependencies.png" alt="Explicitely declared and isolated dependencies" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>3</td>
      <td><strong>Config</strong></td>
      <td>Store config in the environment, not in code</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/strict_separation_of_config_from_code.png" alt="Strict separation of config from code" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>4</td>
      <td><strong>Backing Services</strong></td>
      <td>Treat backing services (DB, cache, queue) as attached resources</td>
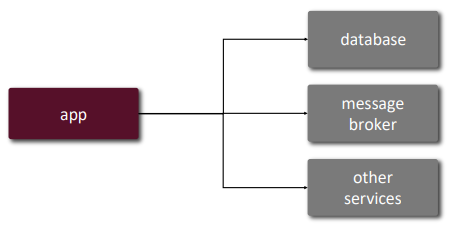
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/backing_service_as_resources.png" alt="Treat backing service as resources" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>5</td>
      <td><strong>Build, Release, Run</strong></td>
      <td>Strictly separate build and run stages</td>
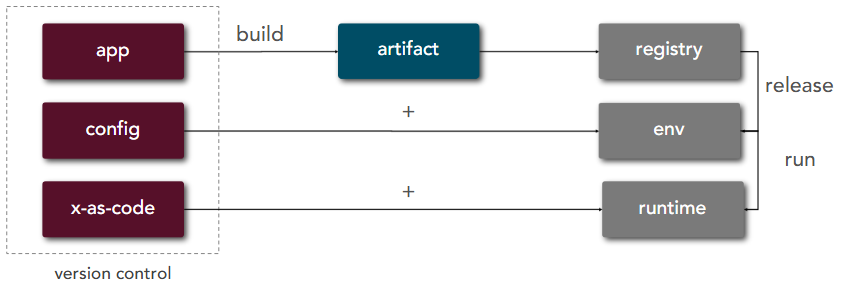
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/build_release_run.png" alt="Build, Release, Run" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>6</td>
      <td><strong>Processes</strong></td>
      <td>Execute the app as one or more stateless processes</td>
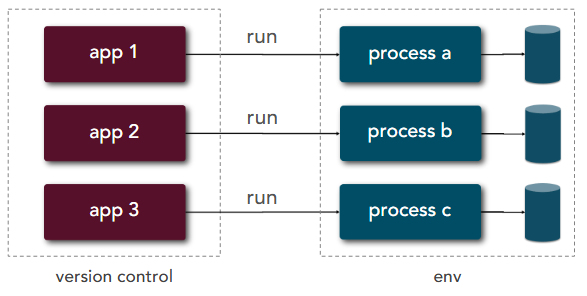
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/execute_as_stateless_processes.png" alt="Execute as one or more stateless processes" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>7</td>
      <td><strong>Port Binding</strong></td>
      <td>Export services via port binding</td>
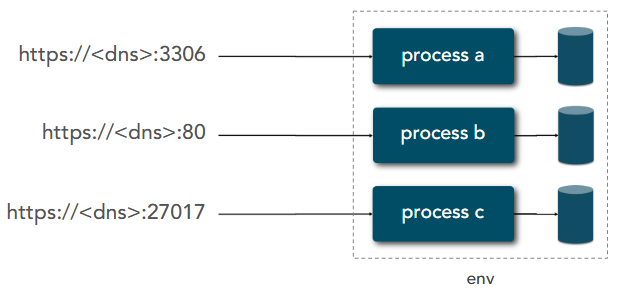
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/export_services_via_port_binding.png" alt="Export services via port binding" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>8</td>
      <td><strong>Concurrency</strong></td>
      <td>Scale out via the process model</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/scale_via_process_model.png" alt="Scale out via the process model" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>9</td>
      <td><strong>Disposability</strong></td>
      <td>Maximise robustness with fast startup and graceful shutdown</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/fast_startup_graceful_shutdown.png" alt="Fast startup and graceful shutdown" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>10</td>
      <td><strong>Dev/Prod Parity</strong></td>
      <td>Keep development, staging, and production as similar as possible</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/reduce_gaps_between_prod_n_dev.png" alt="Development, staging, and production as similar as possible" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>11</td>
      <td><strong>Logs</strong></td>
      <td>Treat logs as event streams</td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/logs_as_event_stream.png" alt="Logs as event streams" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>12</td>
      <td><strong>Admin Processes</strong></td>
      <td>Run admin/management tasks as one-off processes</td>
      <td> </td>
      <td> </td>
    </tr>
    <tr>
      <td>13</td>
      <td><strong>API First</strong></td>
      <td> </td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/.png" alt="" /></td>
      <td> </td>
    </tr>
    <tr>
      <td>14</td>
      <td><strong>Telemetry</strong></td>
      <td> </td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/telemetry.png" alt="Telemetry" /></td>
      <td> </td>
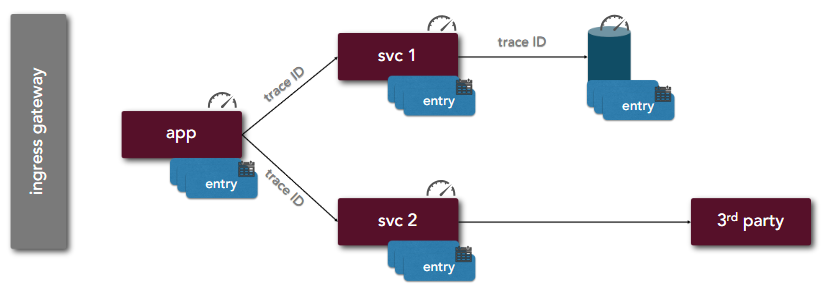
    </tr>
    <tr>
      <td>15</td>
      <td><strong>Authorisation/Authentication</strong></td>
      <td> </td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/auth.png" alt="Authorisation/Authentication" /></td>
      <td>defence_in_depth_layers</td>
    </tr>
    <tr>
      <td>15</td>
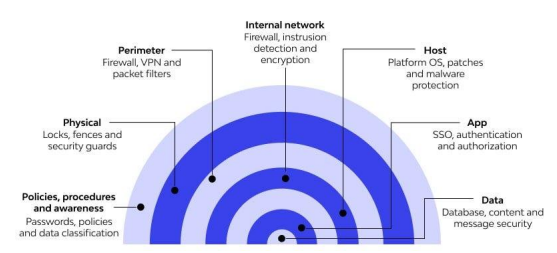
      <td><strong>Defence in depth layers</strong></td>
      <td> </td>
      <td><img src="../assets/images/posts/architecture_patterns_and_antipatterns/defence_in_depth_layers.png" alt="Defence in depth layers" /></td>
      <td> </td>
    </tr>
  </tbody>
</table>

<p>User case:</p>
<ul>
  <li>cloud-nativeability</li>
  <li>security</li>
  <li>scalability</li>
  <li>resilience</li>
  <li>observability</li>
</ul>

<h2 id="deployment-strategies">Deployment Strategies</h2>
<p>3 deployment strategies:</p>
<ol>
  <li>Rolling deploys =&gt; one environment at a time</li>
  <li>Blue-green =&gt; 2 sets of environments: blue (live) and green (new features)</li>
  <li>Canary releases =&gt; hybrid between the 2: rolling traffic percentage between 2 sets of environments (blue and green)
 Benefits of canary release:
    <ul>
      <li>reduced risk of release</li>
      <li>multi-variant testing</li>
      <li>performance testing</li>
    </ul>
  </li>
</ol>

<hr />

<h1 id="ai-patterns">AI Patterns</h1>

<h2 id="rag-retrieval-augmented-generation">RAG (Retrieval Augmented Generation)</h2>

<h2 id="few-shot-prompting">Few-Shot Prompting</h2>
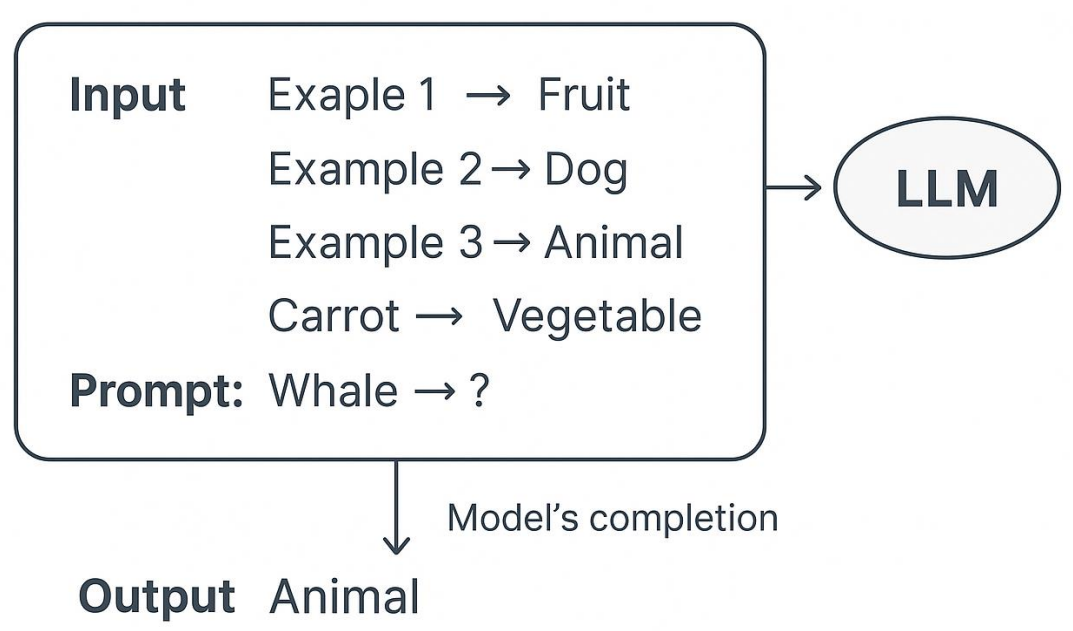
<p>=&gt; guided prompting technique using 2-5 examples for a new similar task.
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/few_shot_prompting.png" alt="Few-shot prompting" /></p>

<h2 id="dynamic-few-shot-prompting">Dynamic Few-Shot Prompting</h2>

<h2 id="on-device-llm-inference">On-Device LLM Inference</h2>
<p>Benefits:</p>
<ul>
  <li>more secure handling of sensitive data</li>
  <li>extremely low latency (including video processing)</li>
  <li>reduced cost</li>
  <li>better reliability</li>
</ul>

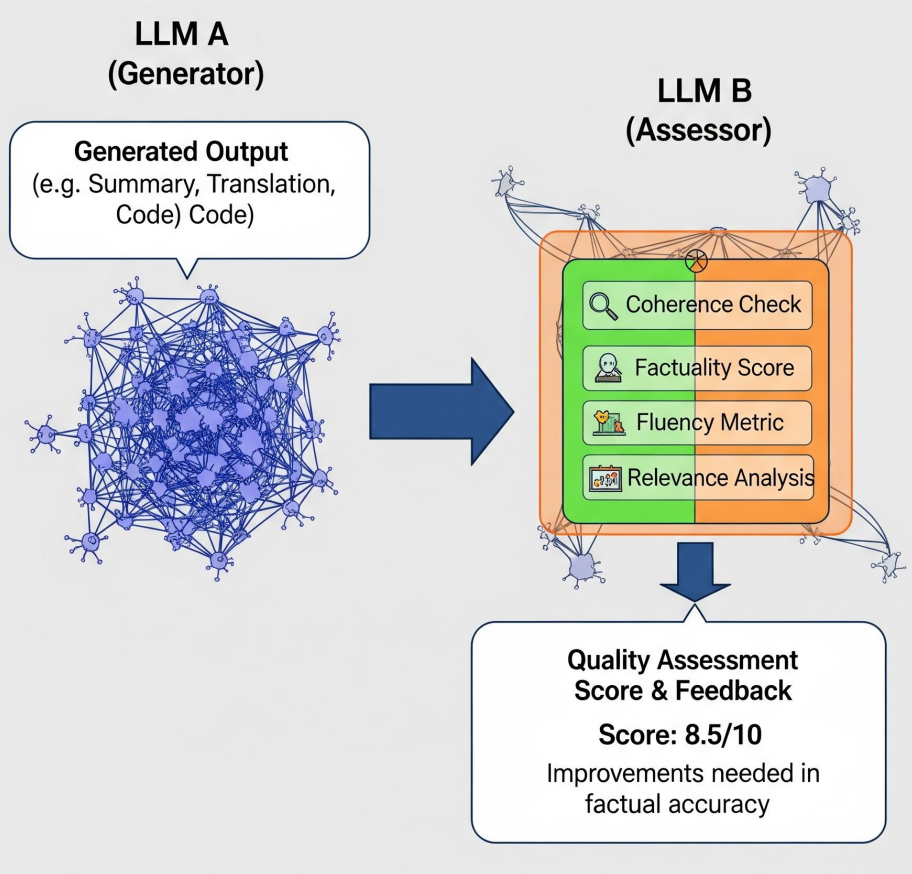
<h2 id="llm-as-judge">LLM-as-Judge</h2>
<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/llm_as_judge.png" alt="LLM-as-Judge" /></p>

<h1 id="ai-anti-patterns">AI Anti-patterns</h1>

<h2 id="halucinated-dependencies-as-attack-factor">Halucinated Dependencies as Attack Factor</h2>
<p>=&gt; a potential security attack by bad actors due to dependency containing malicious code.</p>

<h1 id="architecture-anti-patterns">Architecture Anti-Patterns</h1>

<h2 id="architecture-by-implication">Architecture by Implication</h2>
<p>=&gt; system lacking a clear documented architecture.</p>

<p>Some important details in architecture documents:</p>
<ul>
  <li>What architecture pattern are you using?</li>
  <li>What client model is most appropriate?</li>
  <li>Which platform is best for this solution?</li>
  <li>Does the hardware or os matter?</li>
  <li>How will you handle component integration?</li>
  <li>Which communication protocols should you use?</li>
  <li>Is the solution feasible given skills, budget, and time?</li>
  <li>How secure does the system need to be?</li>
  <li>Does the system need to scale?</li>
  <li>How much performance is needed from the system?</li>
  <li>How available does the system need to be?</li>
  <li>Do you need to be concerned about maintainability?</li>
</ul>

<h2 id="gold-plating">Gold Plating</h2>
<p>=&gt; continuing to define the architecture well past the point which the extra effort is adding any value</p>

<ul>
  <li>Too many details hide the core principles and standards commonly leads to the analysis paralysis anti-pattern in that the initial architecture is never actually released</li>
  <li>Adding gold plating to a well-defined architecture significantly increases costs with little or no value</li>
  <li>A complex and overly-detailed architecture is hard to understand and comprehend =&gt; no “big picture”</li>
</ul>

<h2 id="covering-your-assets">Covering Your Assets</h2>
<p>=&gt; continuing to document and present alternatives without ever making an architecture decision.</p>

<blockquote>
  <p><strong>Architect’s job</strong>: present alternatives, articulate the pros and cons, and recommend best solution.</p>
</blockquote>

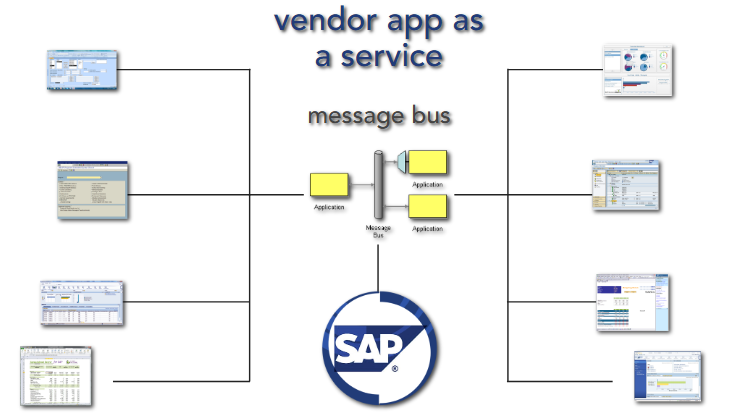
<h2 id="vendor-king">Vendor King</h2>
<p>=&gt; product-dependent architectures leading to a loss of control of architecture and development costs.</p>

<p>Avoidance techniques:</p>
<ul>
  <li>treat vendor app as a service (integration point), not the central of your system</li>
  <li>anti-corruption layer using message bus</li>
</ul>

<p><img src="../assets/images/posts/architecture_patterns_and_antipatterns/vendor_app_as_service.png" alt="Vendor as a service" /></p>

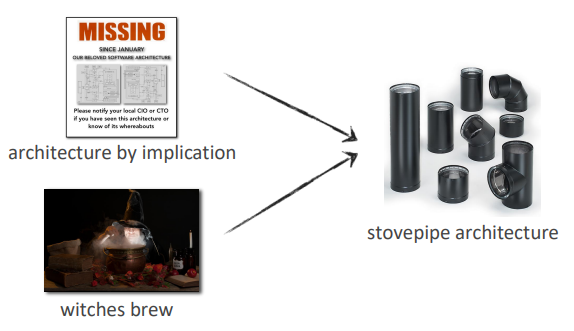
<h2 id="witches-brew">Witches Brew</h2>
<p>=&gt; architectures are designed by groups resulting in a complex mixture of ideas and lack of clear vision</p>

<h2 id="big-bang-architecture">Big Bang Architecture</h2>
<p>=&gt; designing the entire architecture at the beginning of the project when you know least about the system.</p>

<ul>
  <li>Only architect what is absolutely necessary to get the project started and on the right track</li>
  <li>Let the architecture evolve throughout the project as you discover and learn more about the system</li>
  <li>Don’t forget - requirements, technology, and business needs change constantly - and so must the architecture</li>
</ul>

<h2 id="armchair-architecture">Armchair Architecture</h2>
<p>=&gt; whiteboard sketches are handed off as final architecture standards without proving out the design. Be an integral part of your development team!!</p>

<ul>
  <li>occurs when you have non-coding architects</li>
  <li>occurs when architects are not involved in the full project lifecycle</li>
  <li>occurs when architects don’t know what they are doing</li>
  <li>stay current and try to carve out some coding for yourself, even if it is proof-of-concept code</li>
  <li>the best architects are the ones who have been in the trenches themselves and know the fallout from bad architecture decisions</li>
  <li>be careful not to release architecture decisions and standards too early</li>
</ul>

<h2 id="infinity-architecture">Infinity architecture</h2>
<p>=&gt; creating architectures and interfaces that are overgeneralized with infinite flexibility.</p>

<ul>
  <li>generalized architectures that solve every possible need are expensive and difficult to maintain and change - “we may need…”</li>
  <li>instead, use domain-specific architectures to <em>reduce</em> architecture and system scope</li>
</ul>

<h2 id="playing-with-new-toys">Playing With New Toys</h2>
<p>=&gt; incorporating unproven technologies into an architecture that don’t really fit the problem at hand.</p>

<p>when introducing a new technology, ask yourself:</p>
<ul>
  <li>purpose: what value is it delivering?</li>
  <li>proven: is this a proven technology for your situation?</li>
  <li>overlap: is there something we have that is already supplying this functionality?</li>
  <li>feasibility: does your team have the skills necessary for the technology?</li>
</ul>

<h2 id="groundhog-day">Groundhog Day</h2>
<ul>
  <li>critical architecture decisions made early on are lost, forgotten, or not communicated effectively</li>
</ul>

<p>Symptoms and consequences:</p>
<ul>
  <li>people forget or don’t know a decision was made</li>
  <li>the same decision keeps getting discussed and made over and over and over…</li>
  <li>no one understands why a decision was made and they begin to question it again and again…</li>
</ul>

<p>Avoidance technique:</p>
<ul>
  <li>capture all important architecture decisions in some sort of work product (doc, wiki, etc.) and make it centrally available</li>
  <li>make sure the right stakeholders know about critical decisions and where to find them</li>
</ul>

<h2 id="spider-web-architecture">Spider Web Architecture</h2>
<p>=&gt; creating large numbers of web services that are never used just because you can.</p>

<ul>
  <li>just because you can create a web service at the click of a button doesn’t mean you should!</li>
  <li>let the requirements and business needs drive what services should be exposed</li>
</ul>

<h2 id="stovepipe-architecture">Stovepipe Architecture</h2>
<p>=&gt; an ad-hoc collection of ill-related ideas, concepts, and components that leads to a brittle architecture.</p>

<p>Architecture by Implication anti-pattern combined with Witches Brew anti-pattern often leads to Stovepipe Architecture anti-pattern.
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/combo_for_stovepipe.png" alt="Formation leading to Stove Pipe anti-pattern" /></p>

<p>Symptoms and consequences:</p>
<ul>
  <li>lack of proper abstraction</li>
  <li>lack of an integration solution</li>
  <li>lack of architecture guidance</li>
  <li>architectures that are difficult to change, difficult to maintain, and break every time you change something</li>
</ul>

<h1 id="modern-trade-off-analysis">Modern Trade-off Analysis</h1>
<p>Use <strong><em>qualitative</em></strong> analysis to iterate on design, leading to <strong><em>quantitative</em></strong> analysis.</p>

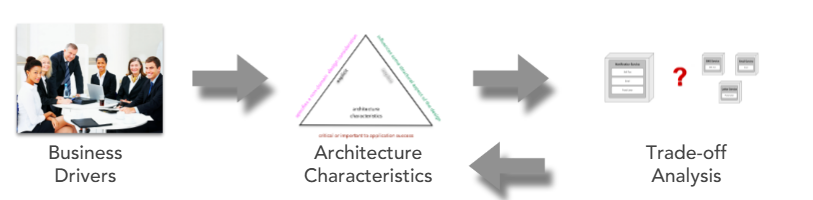
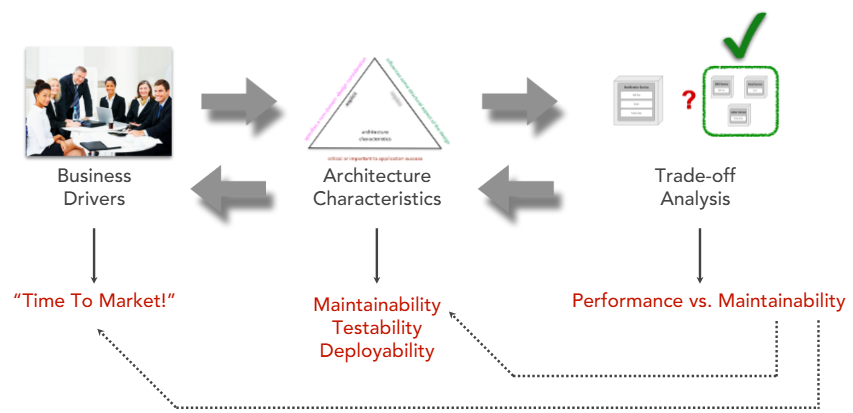
<p>A business driver will translate to a set of architectural characteristics which lead to an analysis trade-off by an architect:
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/tradeoff_analysis_process.png" alt="Business drivers leads to trade-off analysis" /></p>

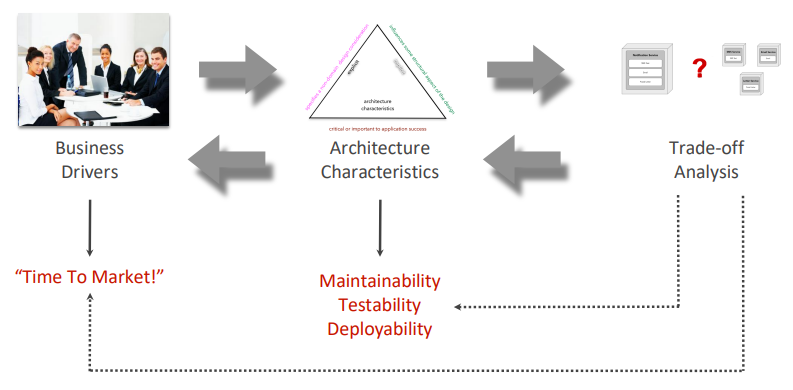
<p>Example:
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/tradeoff_analysis_process_sample.png" alt="Example of trade-off analysis driven by business drives" /></p>

<p>2 useful principles:
| Feature | Goldilock Principle | Good-enough Principle |
|—|—|—|
| Goal | Find the optimal/exact “sweet spot” | Stop at “sufficient” to save time/energy |
| Metaphor | “Just right” | “Done is better than perfect” | 
| Main Use | Balancing variables (e.g., stress, speed) | Decision-making and productivity|</p>

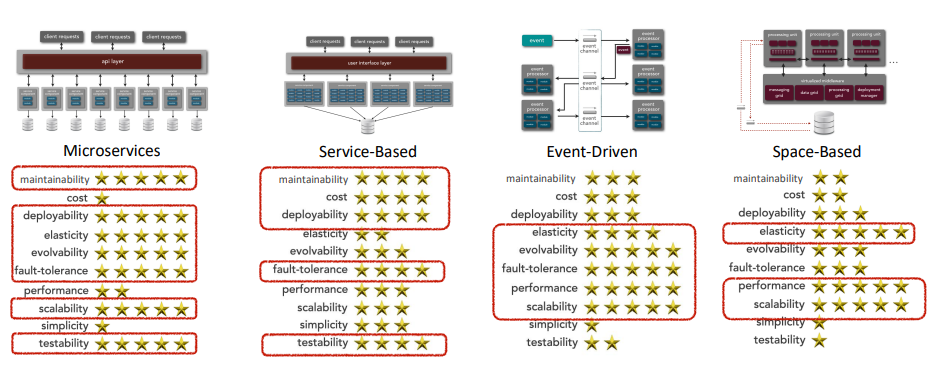
<p>Architecture styles and their best characteristics:
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/arch_styles_best_characteristics.png" alt="Architecture styles and their best characteristics" /></p>

<p>Diagram for trade-off analysis:
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/analysing_architecture_tradeoff.png" alt="Analysing architecture trade-off" /></p>

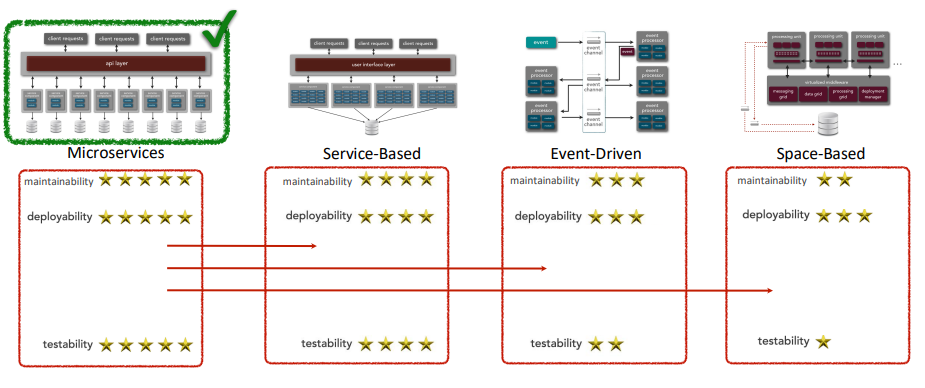
<p>For example, if the desired architecture characteristics are maintainability, testability, and deployability, then the best architecture style for this scenario is microservices, followed by service-based, event-driven, and space-based:
<img src="../assets/images/posts/architecture_patterns_and_antipatterns/architecture_in_competition.png" alt="Finding best architecture styles for your need" /></p>

<p>To build your own qualitative analysis:</p>
<ol>
  <li>Choose a suitable scale: e.g. 5 stars =&gt; 20% per star</li>
  <li>Choose high value criteria</li>
</ol>

<h2 id="architecture-fitness-function">Architecture Fitness Function</h2>
<p>=&gt; provides an <strong>objective</strong> integrity assessment of some architectural characteristic(s).</p>

<hr />

<h1 id="software-architecture-laws">Software Architecture Laws</h1>
<ol>
  <li>Everything is a trade-off. Correlation to this is that the architecture analysis inever done just once.</li>
  <li>Why is more important than how</li>
  <li>Most architecture decisions aren’t binary but rather exist on a spectrum between extremes</li>
</ol>

<h1 id="source">Source</h1>

<h2 id="live-events">Live Events:</h2>
<ul>
  <li><a href="https://learning.oreilly.com/live-events/software-architecture-patterns-and-antipatterns/0642572203900/0642572320140/">Software Architecture Patterns and Antipatterns by Neal Ford and Raju Gandhi</a></li>
</ul>

<h2 id="books">Books:</h2>
<ul>
  <li><a href="https://learning.oreilly.com/library/view/software-architecture-patterns/0642572221119/">Software Architecture Patterns, Antipatterns, and Pitfalls by Mark Richards, Neal Ford, Raju Gandhi</a></li>
  <li>[Software Architecture: The Hard Parts by Mark Richards, Neal Ford, Pramod Sadalage, Zhamak Dehghani]((https://learning.oreilly.com/library/view/software-architecture-the/9781492086888/)</li>
</ul>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[I have a new software project. As a solution architect, where should I start?]]></summary></entry><entry><title type="html">Designing Distributed Systems: 8 Transactional Saga Patterns</title><link href="http://www.javarchitect.com/distributed-systems-saga-patterns/" rel="alternate" type="text/html" title="Designing Distributed Systems: 8 Transactional Saga Patterns" /><published>2026-04-24T00:00:00+00:00</published><updated>2026-04-24T00:00:00+00:00</updated><id>http://www.javarchitect.com/distributed-systems-saga-patterns</id><content type="html" xml:base="http://www.javarchitect.com/distributed-systems-saga-patterns/"><![CDATA[<h2 id="coupling">Coupling</h2>

<p>→ the degree of interdependence between software modules and components.</p>

<p>There are two types: <strong>static</strong> and <strong>dynamic</strong>.</p>

<h3 id="static-coupling">Static Coupling</h3>

<p>→ fixed, code/deployment-level dependencies.</p>

<p>Example: a shared library, or direct code references — regardless of whether services are actively communicating.</p>

<h3 id="dynamic-coupling">Dynamic Coupling</h3>

<p>→ runtime dependencies.</p>

<p>Example: when Service A calls Service B <em>synchronously</em>, A becomes temporarily coupled to B’s:</p>

<ul>
  <li><strong>Availability</strong> — if B is down, A fails too</li>
  <li><strong>Performance</strong> — if B is slow, A is slow</li>
  <li><strong>Error behaviour</strong> — B’s errors propagate directly to A</li>
</ul>

<h3 id="transactional-coupling">Transactional Coupling</h3>

<p>→ data processing dependencies.</p>

<p>Example: a customer request involves an update to 3 tables in a database. For this update to be atomic, all 3 transaction updates should happen or nothing at all.</p>

<h3 id="contract-coupling">Contract Coupling</h3>
<p>→ data transfer level: data exchange between microservices should agree on the data format being exchange (JSON schema, XML schema, RPC, etc).</p>

<p>More details on Managing Contracts section below.</p>

<h3 id="temporal-coupling">Temporal Coupling</h3>
<p>→ availability of the interacting microservices.</p>

<p>Example: microservice A requires microservice B to be available at a specific time to perform some functionality.</p>

<hr />

<h2 id="the-three-primal-dynamic-coupling-forces">The Three Primal Dynamic-Coupling Forces</h2>

<p>Every distributed system is shaped by three fundamental tensions:</p>

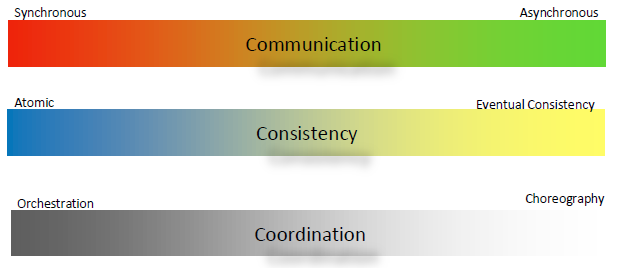
<p><img src="../assets/images/posts/distributed_systems_saga_patterns/primal_dynamic_coupling_forces.png" alt="Spectrum of primal dynamic coupling forces" title="Dynamic coupling forces" /></p>

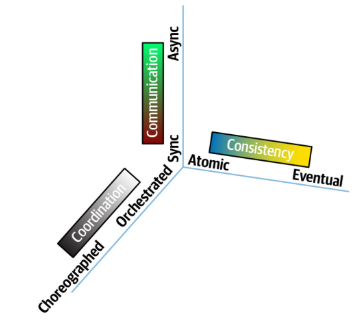
<p>Each of these forces is acting in their own spectrum axis which combine to form the 8 saga patterns covered later in Section 4.</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/dynamic_coupling_forces_axes.png" alt="Dynamic coupling forces axes" title="Dynamic coupling forces" /></p>

<table>
  <thead>
    <tr>
      <th>Force</th>
      <th>Options</th>
      <th>Impact on Distributed System Characteristics</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Communication</strong></td>
      <td>Synchronous ↔ Asynchronous</td>
      <td>★★</td>
    </tr>
    <tr>
      <td><strong>Consistency</strong></td>
      <td>Atomic ↔ Eventual</td>
      <td>★★★</td>
    </tr>
    <tr>
      <td><strong>Coordination</strong></td>
      <td>Orchestration ↔ Choreography</td>
      <td>★</td>
    </tr>
  </tbody>
</table>

<p>The impacts of each of these driving forces will become apparent when we compare 8 different types of sagas based on the permutation of the options.</p>

<hr />

<h2 id="1-communication">1. Communication</h2>

<h3 id="synchronous-vs-asynchronous">Synchronous vs. Asynchronous</h3>

<table>
  <thead>
    <tr>
      <th>Synchronous</th>
      <th>Asynchronous</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Tasks run in order</td>
      <td>Tasks run independently</td>
    </tr>
    <tr>
      <td>Often blocking the thread</td>
      <td>Using callbacks for completion</td>
    </tr>
  </tbody>
</table>

<h4 id="blocking-vs-non-blocking">Blocking vs. Non-blocking</h4>
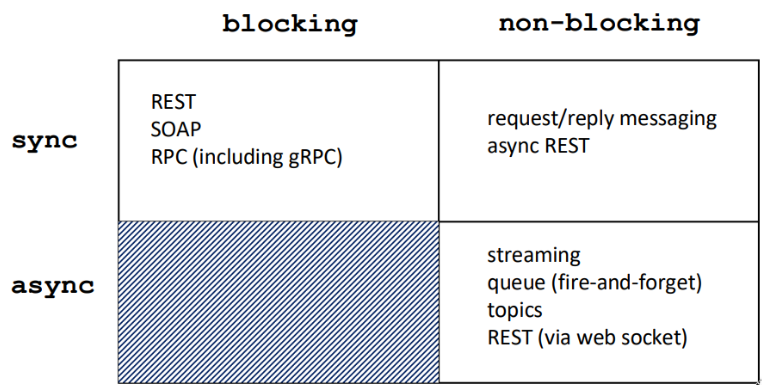
<p>Subtle difference between synchronous/asynchronous and blocking/non-blocking:</p>

<table>
  <thead>
    <tr>
      <th>Synchronous/Asynchronous</th>
      <th>Blocking/Non-blocking</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>On a system level</td>
      <td>On a thread level</td>
    </tr>
    <tr>
      <td>Relates to when a task finishes and how the result is handled (flow control)</td>
      <td>Relates to whether the thread is suspended while waiting for a task (resource state)</td>
    </tr>
  </tbody>
</table>

<h4 id="examples">Examples</h4>

<ul>
  <li>
    <p><strong>Synchronous &amp; Blocking (Standard)</strong>: You call a function, and your code stops (blocks) and waits for the result before moving to the next line.
Example: Reading a large file from disk; the program pauses until the file is fully loaded.</p>
  </li>
  <li>
    <p><strong>Synchronous &amp; Non-blocking</strong>: You start a task and immediately get control back (non-blocking), but you must manually check back (polling) until the task is complete. 
Example: Starting a download, then checking the progress bar every few seconds, but you still wait for that specific download to finish to proceed.</p>
  </li>
  <li>
    <p><strong>Asynchronous &amp; Blocking (Rare/Inefficient)</strong>: The task runs in the background (asynchronous), but you still stop and wait for it to finish.
Example: Starting a background task, but immediately sitting idle waiting for the “done” notification.</p>
  </li>
  <li>
    <p><strong>Asynchronous &amp; Non-blocking (Modern)</strong>: You start a task and immediately move on to other work (non-blocking). When the task finishes, you are notified (asynchronous).
Example: Sending an API request with a callback function; the main thread continues executing other code and handles the result only when the request completes.</p>
  </li>
</ul>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/sync_async_blocking_nonblocking_combinations.png" alt="Sample of sync/async blocking/non-blocking combinations" title="Sample of sync/async blocking/non-blocking combinations" /></p>

<h4 id="architectural-quantum">Architectural Quantum</h4>

<blockquote>
  <p><em>An architecture quantum establishes the scope for a set of architectural characteristics.</em></p>
</blockquote>

<p>Characteristics of a quantum:</p>
<ul>
  <li><strong>Independent</strong> deployment</li>
  <li>High functional cohesion</li>
  <li>Low external-implementation static coupling</li>
  <li><strong>Synchronous</strong> communication with other quanta</li>
</ul>

<p><strong>Synchronous calls</strong> create <em>“dynamic quantum entanglement”</em> — they couple the operational characteristics of separate services. A slow or unavailable downstream service degrades the entire call chain, i.e. the weakest characteristic of a service becomes the characteristic of the system.</p>

<blockquote>
  <p><em>**Your system is only as good as the least characteristics  **</em></p>
</blockquote>

<p><strong>Asynchronous calls</strong>, on the other hand, retains the architecture quantum of individual services in a system.</p>

<p>Example:</p>

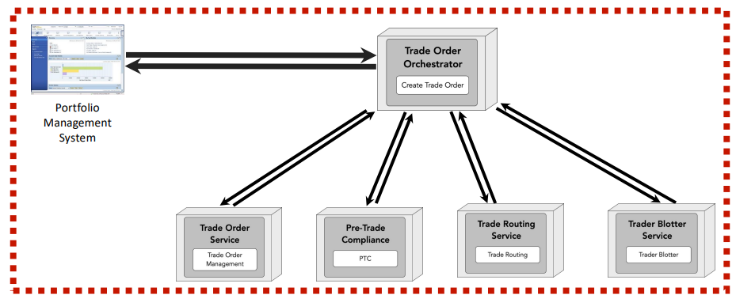
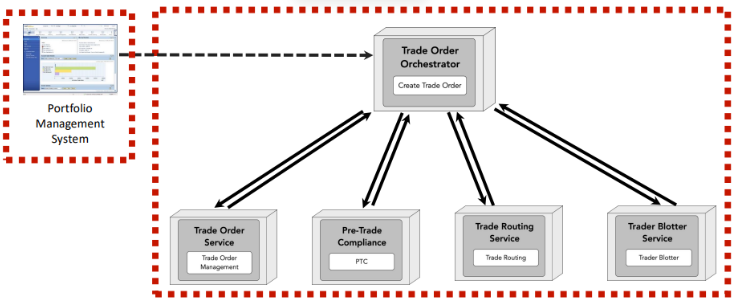
<p><img src="../assets/images/posts/distributed_systems_saga_patterns/sample_problem.png" alt="Architectural quanta: sample case" title="Study case: 2 architectural quanta - Portfolio Management System &amp; Trade Order Orchestrator" /></p>

<p>In the above picture, the microservices on the right side form 1 architectural quanta because of the <strong>synchronous communication</strong> among the services.</p>

<p>When Portfolio Management System communicates with Trade Order Orchestrator, 2 things can happen:</p>

<ol>
  <li>If they communicate synchronously, they form into 1 architectural quantum =&gt; architectural characteristics drop to the lower level in the workflow.</li>
</ol>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/study_case_1_quantum.png" alt="2 architectural quanta becomes 1 architectural quantum" title="2 architectural quanta becomes 1 architectural quantum" /></p>

<ol>
  <li>If they communicate asynchronously, they stay separated as 2 architectural quanta =&gt; architectural characteristics are retained.</li>
</ol>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/study_case_2_quanta.png" alt="Architectural quanta are retained" title="Architectural quanta are retained" /></p>

<blockquote>
  <p><em>So how do we determine the communication type should be synchronous or asynchronous?</em></p>

  <p>It depends on <strong>whether the service needs to wait</strong> for the response from another service. If so, then it’s synchronous.</p>

  <p>Also for simplicity, default to synchronous communication. <strong>Synchronous</strong> → <strong>simpler</strong></p>
</blockquote>

<h4 id="trade-off-summary">Trade-off Summary</h4>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Synchronous</th>
      <th>Asynchronous</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Easy to reason about</td>
      <td>✅</td>
      <td> </td>
    </tr>
    <tr>
      <td>Mimics non-distributed calls</td>
      <td>✅</td>
      <td> </td>
    </tr>
    <tr>
      <td>Easier to implement</td>
      <td>✅</td>
      <td> </td>
    </tr>
    <tr>
      <td>Highly decoupled</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>High performance and scale</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>Common performance tuning technique</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>Performance impact on interactive systems</td>
      <td>⚠️</td>
      <td> </td>
    </tr>
    <tr>
      <td>Creates dynamic quantum entanglements</td>
      <td>⚠️</td>
      <td> </td>
    </tr>
    <tr>
      <td>Complex to build and debug</td>
      <td> </td>
      <td>⚠️</td>
    </tr>
    <tr>
      <td>Difficult for transactional behaviour</td>
      <td> </td>
      <td>⚠️</td>
    </tr>
    <tr>
      <td>Complex error handling</td>
      <td> </td>
      <td>⚠️</td>
    </tr>
  </tbody>
</table>

<hr />

<h3 id="managing-contracts">Managing Contracts</h3>

<p>When a service calls a method in another service, it’s a <strong>contract</strong> between the 2 services of what the request and response formats should be like.</p>

<h4 id="strict-vs-loose-contracts">Strict vs. Loose Contracts</h4>

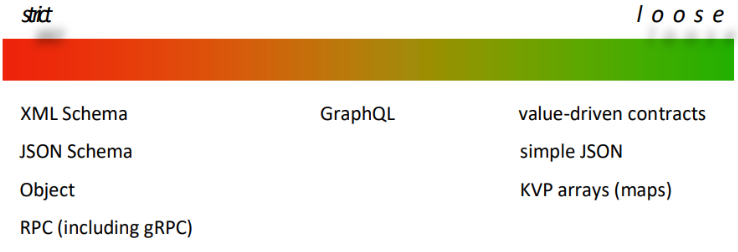
<p><img src="../assets/images/posts/distributed_systems_saga_patterns/contract_spectrum.png" alt="Contract spectrum" title="Contract spectrum" /></p>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Tight (Strict)</th>
      <th>Loose</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Guaranteed contract fidelity</td>
      <td>✅</td>
      <td> </td>
    </tr>
    <tr>
      <td>Build-time validation</td>
      <td>✅</td>
      <td> </td>
    </tr>
    <tr>
      <td>Better for decoupled architectures</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>Easier to evolve</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>Decouples integration from implementation platform</td>
      <td> </td>
      <td>✅</td>
    </tr>
    <tr>
      <td>Brittle integration points</td>
      <td>⚠️</td>
      <td> </td>
    </tr>
    <tr>
      <td>Requires versioning</td>
      <td>⚠️</td>
      <td> </td>
    </tr>
    <tr>
      <td>Less certainty; needs fitness functions</td>
      <td> </td>
      <td>⚠️</td>
    </tr>
    <tr>
      <td>Requires developer discipline</td>
      <td> </td>
      <td>⚠️</td>
    </tr>
  </tbody>
</table>

<p><strong>Principle:</strong> <em>Transfer values, not types.</em> Value-based (loose) contracts decouple consumers from implementation changes.</p>

<h4 id="contract-fitness-functions">Contract Fitness Functions</h4>

<p>Consumer-Driven Contracts (CDCs) can automate contract verification.</p>

<p>The <strong>Pact</strong> framework (<a href="https://docs.pact.io">docs.pact.io</a>) supports this for REST and event-driven architectures, with CI/CD integration.</p>

<hr />

<h3 id="event-payload-design">Event Payload Design</h3>

<blockquote>
  <p><em>Should an event carry the <strong>full data payload</strong> or just <strong>key identifiers</strong>?</em></p>
</blockquote>

<table>
  <thead>
    <tr>
      <th>Trade-off Dimension</th>
      <th>Full Payload</th>
      <th>Key-Only Payload</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Scalability &amp; performance</td>
      <td>✅ Good</td>
      <td>⚠️ Poor</td>
    </tr>
    <tr>
      <td>Contract management &amp; versioning</td>
      <td>⚠️ Complex</td>
      <td>✅ Simple</td>
    </tr>
    <tr>
      <td>Single system of record</td>
      <td>⚠️ Multiple</td>
      <td>✅ Single</td>
    </tr>
    <tr>
      <td>Stamp coupling &amp; bandwidth</td>
      <td>⚠️ High</td>
      <td>✅ Low</td>
    </tr>
  </tbody>
</table>

<blockquote>
  <p><strong><em>Choose Key-Only Payload if scalability and performance are not the priority</em></strong></p>
</blockquote>

<p><strong>Stamp coupling example:</strong> A customer profile returning 500 KB payloads at 2,000 req/s uses ~1,000,000 KB/s of bandwidth. Returning only required fields (~200 bytes) reduces this to ~400 KB/s — a <strong>2,500× reduction</strong>.</p>

<blockquote>
  <p><strong>Looser contracts create less brittle software architectures.</strong></p>
</blockquote>

<hr />

<h2 id="2-coordination">2. Coordination</h2>

<h3 id="orchestration-vs-choreography">Orchestration vs. Choreography</h3>

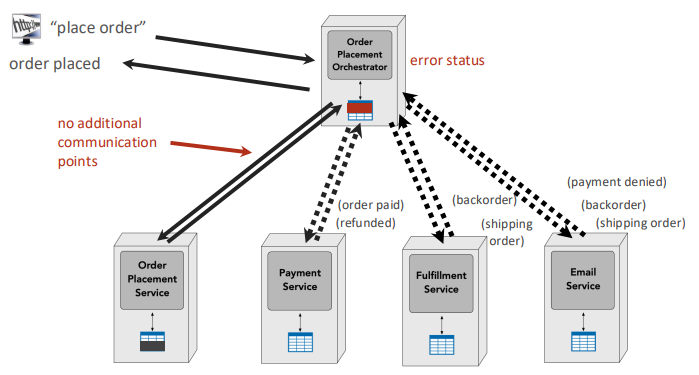
<h4 id="orchestration">Orchestration</h4>

<ul>
  <li>generally one orchestrator per major workflow</li>
  <li>orchestrator owns state and communicates update points to services</li>
</ul>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/orchestration.png" alt="Orchestration" title="Orchestration" /></p>

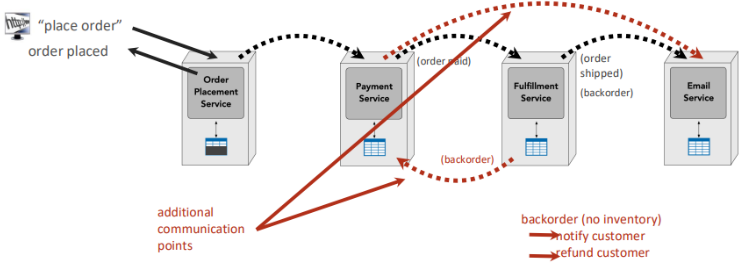
<h4 id="choreography">Choreography</h4>

<ul>
  <li>services react to events</li>
  <li>no central controller</li>
  <li>the workflow emerges from the chain of events</li>
</ul>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/choreography.png" alt="Choreography" title="Choreography" /></p>

<h4 id="hybrids">Hybrids</h4>

<ul>
  <li>an orchestrated outer workflow can delegate to choreographed sub-workflows</li>
</ul>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/hybrid.png" alt="Hybrids" title="Hybrids" /></p>

<h4 id="summary">Summary</h4>

<table>
  <thead>
    <tr>
      <th> </th>
      <th>Orchestration</th>
      <th>Choreography</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>State owner</td>
      <td>Central orchestrator</td>
      <td>Distributed across services</td>
    </tr>
    <tr>
      <td>Workflow control</td>
      <td>Centralised → tighter coupling</td>
      <td>Emergent / event-driven → loose coupling</td>
    </tr>
    <tr>
      <td>Error handling</td>
      <td>✅ Easier — one place</td>
      <td>⚠️ Harder — spread across services</td>
    </tr>
    <tr>
      <td>Responsiveness</td>
      <td>Moderate</td>
      <td>✅ High</td>
    </tr>
    <tr>
      <td>Scalability / throughput</td>
      <td>Moderate</td>
      <td>✅ High</td>
    </tr>
    <tr>
      <td>Fault tolerance</td>
      <td>✅ Good</td>
      <td>✅ Better</td>
    </tr>
    <tr>
      <td>Recoverability</td>
      <td>✅ Good</td>
      <td>⚠️ Difficult</td>
    </tr>
    <tr>
      <td>Workflow / state management</td>
      <td>✅ Good</td>
      <td>⚠️ Complex</td>
    </tr>
  </tbody>
</table>

<hr />

<h2 id="3-consistency">3. Consistency</h2>

<h3 id="acid-transactions">ACID Transactions</h3>

<ul>
  <li>
    <p><strong>Atomicity</strong> — all steps in a transaction either fully succeed or fully roll back together; there is no partial completion.</p>
  </li>
  <li>
    <p><strong>Consistency</strong> — a transaction always moves the database from one valid state to another, never leaving data in a corrupt or rule-violating state.</p>
  </li>
  <li>
    <p><strong>Isolation</strong> — concurrent transactions are invisible to each other until committed, so one transaction cannot see another’s in-progress changes.</p>
  </li>
  <li>
    <p><strong>Durability</strong> — once a transaction is committed, the data is permanently saved and survives any subsequent system failure.</p>
  </li>
</ul>

<p>In a distributed context, standard ACID properties break down:</p>

<table>
  <thead>
    <tr>
      <th>Property</th>
      <th>Problem in Distributed Systems</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Atomicity</strong></td>
      <td>Each service commits/rolls back independently — a failure mid-chain leaves partial state</td>
    </tr>
    <tr>
      <td><strong>Consistency</strong></td>
      <td>An error in one service (e.g. inventory) causes data inconsistency across others</td>
    </tr>
    <tr>
      <td><strong>Isolation</strong></td>
      <td>Inserted data may be visible to other services before the overall transaction completes</td>
    </tr>
    <tr>
      <td><strong>Durability</strong></td>
      <td>Data is only made permanent at the service level, not the transaction level</td>
    </tr>
  </tbody>
</table>

<h3 id="base-transactions">BASE Transactions</h3>

<p>As an alternative, <strong>BASE</strong> (<em><strong>B</strong>asically <strong>A</strong>vailable, <strong>S</strong>oft state, <strong>E</strong>ventually consistent</em>) is the natural fit for distributed, decoupled systems.</p>

<h3 id="eventual-consistency-patterns">Eventual Consistency Patterns</h3>

<p><strong>Sample problem</strong>: Deleting a customer in one service must propagate to dependent services (wish list, preferences, etc.).</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/sample_problem.png" alt="Sample problem: deleting customer 123 within Distributed Systems - 1 service done, 2 other still have customer 123 in their DB" title="Sample problem: deleting customer 123 within Distributed Systems - 1 service done, 2 other still have customer 123 in their DB" /></p>

<p>3 patterns for propagating state changes from the sample above:</p>

<ol>
  <li>
    <p><strong>Background Synchronisation</strong> → a background job reads across databases to sync state.<br />
⚠️ Creates direct database coupling between services. <br /> 
<img src="../assets/images/posts/distributed_systems_saga_patterns/background_sync.png" alt="Background Synchronisation" title="Background Synchronisation" /></p>
  </li>
  <li>
    <p><strong>Event-Based Data Synchronisation</strong> → the originating service fires an event; consumers react.<br />
✅ Decoupled. Standard Event-Driven Architecture pattern. <br /> 
<img src="../assets/images/posts/distributed_systems_saga_patterns/event_based_data_sync.png" alt="Event-Based Data Synchronisation" title="Event-Based Data Synchronisation" /></p>
  </li>
  <li>
    <p><strong>Workflow Event Pattern</strong> → a dedicated workflow processor mediates between the event producer and consumers, handling ordering and retries. <br /> 
<img src="../assets/images/posts/distributed_systems_saga_patterns/workflow_event_pattern.png" alt="Workflow Event Pattern" title="Workflow Event Pattern" /></p>
  </li>
</ol>

<hr />

<h3 id="compensating-updates">Compensating Updates</h3>

<p>When a step fails partway through a distributed transaction, previously committed changes must be <strong>compensated</strong> (rolled back manually).</p>

<p><strong>Fallacies of compensating updates:</strong></p>
<ul>
  <li>The compensating update itself may fail</li>
  <li>Side effects may have already occurred (e.g. an email sent, a charge processed)</li>
  <li>State management becomes complex</li>
</ul>

<p><strong>Mitigation (by state management):</strong> Marking data as <code class="language-plaintext highlighter-rouge">WIP (Work-In-Progress)</code> vs <code class="language-plaintext highlighter-rouge">PLACED</code> allows services to avoid querying data not yet in a finalisable state, reducing inconsistency windows.</p>

<blockquote>
  <p>When a system incorporates process for compensating updates, execution logs is crucial for traceability.</p>
</blockquote>

<hr />

<h2 id="4-transactional-sagas">4. Transactional Sagas</h2>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/transactional_sagas.png" alt="Transactional Sagas" title="Transactional Sagas" /></p>

<p>8 Saga patterns can be formed by combining the 3 coupling forces:</p>

<table>
  <thead>
    <tr>
      <th>Saga</th>
      <th>Consistency</th>
      <th>Coordination</th>
      <th>Communication</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Epic Saga</strong></td>
      <td>Atomic</td>
      <td>Orchestration</td>
      <td>Sync</td>
    </tr>
    <tr>
      <td><strong>Fantasy Fiction Saga</strong></td>
      <td>Atomic</td>
      <td>Orchestration</td>
      <td>Async</td>
    </tr>
    <tr>
      <td><strong>Phone Tag Saga</strong></td>
      <td>Atomic</td>
      <td>Choreography</td>
      <td>Sync</td>
    </tr>
    <tr>
      <td><strong>Horror Story Saga</strong></td>
      <td>Atomic</td>
      <td>Choreography</td>
      <td>Async</td>
    </tr>
    <tr>
      <td><strong>Fairy Tale Saga</strong></td>
      <td>Eventual</td>
      <td>Orchestration</td>
      <td>Sync</td>
    </tr>
    <tr>
      <td><strong>Parallel Saga</strong></td>
      <td>Eventual</td>
      <td>Orchestration</td>
      <td>Async</td>
    </tr>
    <tr>
      <td><strong>Time Travel Saga</strong></td>
      <td>Eventual</td>
      <td>Choreography</td>
      <td>Sync</td>
    </tr>
    <tr>
      <td><strong>Anthology Saga</strong></td>
      <td>Eventual</td>
      <td>Choreography</td>
      <td>Async</td>
    </tr>
  </tbody>
</table>

<hr />

<h3 id="saga-descriptions">Saga Descriptions</h3>

<h4 id="️-epic-saga--a-long-running-heroic-story">🗡️ Epic Saga — <em>“A long-running, heroic story”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_epic_saga.png" alt="Epic Saga star rating" title="Epic Saga star rating" /></p>

<ul>
  <li>Mimics a non-distributed transactional interaction</li>
  <li>Holistic transactional coordination increases coupling</li>
  <li>Easy to understand; difficult to implement</li>
</ul>

<p><strong>Use when:</strong> Each step must complete before the next starts; absolute transactionality matters more than responsiveness.</p>

<hr />

<h4 id="-fantasy-fiction-saga--a-complex-story-thats-hard-to-believe-in-the-end">📖 Fantasy Fiction Saga — <em>“A complex story that’s hard to believe in the end”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_fantasy_fiction_saga.png" alt="Fantasy Fiction Saga star rating" title="Fantasy Fiction Saga star rating" /></p>

<ul>
  <li>Moving to async communication improves performance/responsiveness…</li>
  <li>…but introduces concurrency issues that may be worse than the original performance problems</li>
</ul>

<p><strong>Use when:</strong> A first attempt at improving an Epic Saga; responsiveness matters more than strict ordering.</p>

<hr />

<h4 id="-fairy-tale-saga--an-easy-story-with-a-pleasant-ending">🏡 Fairy Tale Saga — <em>“An easy story with a pleasant ending”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_fairy_tale_saga.png" alt="Fairy Tale Saga star rating" title="Fairy Tale Saga star rating" /></p>

<ul>
  <li>Sync + orchestrated = easiest to reason about</li>
  <li>The <strong>Orchestrated Saga</strong> in <a href="https://learning.oreilly.com/library/view/-/9781617294549/">Chris Richardson’s Microservices Patterns</a> book</li>
</ul>

<p><strong>Use when:</strong> Medium to complex workflows that don’t need extreme scale. <strong>Default choice for most situations.</strong></p>

<hr />

<h4 id="-parallel-saga--multiple-stories-running-at-the-same-time">⚡ Parallel Saga — <em>“Multiple stories running at the same time”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_parallel_saga.png" alt="Parallel Saga star rating" title="Parallel Saga star rating" /></p>

<ul>
  <li>Orchestrator allows complex workflows with concurrency</li>
  <li>Highly attractive for complex workflows at high scale</li>
  <li>Difficult if ordering of updates matters</li>
</ul>

<hr />

<h4 id="-phone-tag-saga--like-the-game-of-phone-tag">📞 Phone Tag Saga — <em>“Like the game of phone tag”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_phone_tag_saga.png" alt="Phone Tag Saga star rating" title="Phone Tag Saga star rating" /></p>

<ul>
  <li>An unusual combination: atomic + choreography</li>
  <li>Adds scalability to a simple transactional workflow when the orchestrator becomes a bottleneck</li>
  <li>Not common in practice</li>
</ul>

<hr />

<h4 id="-horror-story-saga--a-nightmare">😱 Horror Story Saga — <em>“A nightmare”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_horror_story_saga.png" alt="Horror Story Saga star rating" title="Horror Story Saga star rating" /></p>

<ul>
  <li>Attempts atomic workflows without a coordinator, with concurrency on top</li>
  <li>Workflow, error handling, boundary conditions, and transactionality are spread across domain services</li>
  <li>Middling performance coupled with impossible-to-reproduce errors</li>
  <li>Actually an <strong><em>anti-pattern</em></strong></li>
</ul>

<p>⚠️ <strong>Not uncommon in practice.</strong> Usually a well-intentioned but flawed attempt to achieve high performance with atomicity.</p>

<hr />

<h4 id="-time-travel-saga--a-problem-that-moves-atomically-through-time">⏳ Time Travel Saga — <em>“A problem that moves atomically through time”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_time_travel_saga.png" alt="Time Travel Saga star rating" title="Time Travel Saga star rating" /></p>

<ul>
  <li>No orchestrator makes complex workflows difficult</li>
  <li>Best for pipeline problems (chain-of-responsibility, pipes-and-filters) with staging or additive workflows</li>
  <li>Works best when synchronous communication is acceptable</li>
</ul>

<hr />

<h4 id="-anthology-saga--a-loosely-associated-group-of-short-stories">📚 Anthology Saga — <em>“A loosely associated group of short stories”</em></h4>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/stars_anthology_saga.png" alt="Anthology Saga star rating" title="Anthology Saga star rating" /></p>

<ul>
  <li>The <strong>Choreographed Saga</strong> in <a href="https://learning.oreilly.com/library/view/-/9781617294549/">Chris Richardson’s Microservices Patterns</a> book</li>
  <li>Polar opposite of the Epic Saga</li>
  <li>Best for non-transactional pipes-and-filters architecture styles</li>
  <li>Highly scalable due to lack of coupling - the least coupled option</li>
</ul>

<hr />

<h3 id="quantitative-trade-off-summary">Quantitative Trade-off Summary</h3>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/dynamic_coupling_forces_axes.png" alt="Dynamic coupling forces axes" title="Dynamic coupling forces" /></p>

<p>Mixing the properties of the 3 axes of dynamic coupling forces, <strong><em>Consistency</em></strong> choice has the greatest impact on saga quality, followed by <strong><em>Coordination</em></strong> style then <strong><em>Communication</em></strong> mode.</p>

<p><strong>Consistency → Coordination → Communication</strong></p>

<table>
  <thead>
    <tr>
      <th>Axis</th>
      <th>Impact on Decoupling / Scalability</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td><strong>Consistency</strong>: <br /> Atomic → Eventual</td>
      <td><strong>+163%</strong> improvement</td>
    </tr>
    <tr>
      <td><strong>Coordination</strong>: <br /> Orchestration → Choreography</td>
      <td><strong>+143%</strong> improvement</td>
    </tr>
    <tr>
      <td><strong>Communcation</strong>: <br /> Sync → Async</td>
      <td><strong>+55%</strong> improvement</td>
    </tr>
  </tbody>
</table>

<hr />

<h3 id="saga-profiles">Saga Profiles</h3>

<p>Below is the 8 transactional sagas score cards:</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/saga_profiles.png" alt="Saga profiles" title="Saga profiles" /></p>

<p>The table above gives a simplified guidance on the system architecture we should have to achieve the characteristic priorities implied.</p>

<p>For example, to have a distributed system with low response latency, the table shows below:</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/responsive_distributed_system_choice.png" alt="Choice of responsive distributed system architecture" title="Choice of responsive distributed system architecture" /></p>

<p>Now the option is just either we want orchestrated or choreographed system. If scalability is the next priority, then anthology saga is the pattern we should follow. If simplicity is, parallel saga is the pattern.</p>

<p>Also from the table we can see that what drives an orchestration system down on scalability and responsiveness is not the orchestration itself but it’s the atomic transactions. Once we tweak the transactions to be eventual consistent, we should expect improvements in responsiveness and scalability of the system.</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/atomic_vs_eventual.png" alt="Atomic vs eventual orchestrated system for better responsiveness and scalability" title="Atomic vs eventual orchestrated system for better responsiveness and scalability" /></p>

<hr />

<h3 id="transactional-sharding">Transactional Sharding</h3>

<p>For very high-volume scenarios, <strong>domain sharding</strong> distributes load across <strong>multiple Saga instances</strong> for better performance/responsiveness.</p>

<p>Example: a concert ticket sale spike can be handled by sharding by seat section or venue zone, avoiding a single transaction bottleneck.</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/domain_sharding.png" alt="Example - transactional sharding by seat section for high volume concert" title="Example - transactional sharding by seat section for high volume concert" /></p>

<p>Domain sharding maps naturally onto microservices: services can be sharded by geography or specialisation, allowing concurrent saga instances without contention.</p>

<p><img src="../assets/images/posts/distributed_systems_saga_patterns/geographical_sharding.png" alt="Example - transactional sharding by geographical location" title="Example - transactional sharding by geographical location" /></p>

<hr />

<h2 id="key-principles-summary">Key Principles Summary</h2>

<table>
  <thead>
    <tr>
      <th>Principle</th>
      <th>Implication</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Synchronous calls create dynamic quantum entanglement</td>
      <td>Default to async where responsiveness and scale matter</td>
    </tr>
    <tr>
      <td>Looser contracts = less brittle software</td>
      <td>Prefer <strong>value-based</strong> contracts in microservices</td>
    </tr>
    <tr>
      <td>Stamp coupling wastes bandwidth</td>
      <td>Send only the data a consumer needs</td>
    </tr>
    <tr>
      <td>ACID breaks in distributed systems</td>
      <td>Accept <strong>eventual consistency</strong> where business rules allow</td>
    </tr>
    <tr>
      <td>Compensating updates have fallacies</td>
      <td>Use state management to reduce inconsistency windows</td>
    </tr>
    <tr>
      <td><strong>Fairy Tale Saga</strong> is the <strong>default</strong></td>
      <td>Use it for most medium-complexity workflows</td>
    </tr>
    <tr>
      <td><strong>Horror Story Saga</strong> is an <strong>antipattern</strong></td>
      <td>Avoid atomic + choreography + async</td>
    </tr>
    <tr>
      <td><strong>Anthology Saga</strong> is the <strong>most scalable</strong></td>
      <td>Use for pipelines that don’t require transactionality</td>
    </tr>
  </tbody>
</table>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[Coupling → the degree of interdependence between software modules and components. There are two types: static and dynamic. Static Coupling → fixed, code/deployment-level dependencies. Example: a shared library, or direct code references — regardless of whether services are actively communicating. Dynamic Coupling → runtime dependencies. Example: when Service A calls Service B synchronously, A becomes temporarily coupled to B’s: Availability — if B is down, A fails too Performance — if B is slow, A is slow Error behaviour — B’s errors propagate directly to A Transactional Coupling → data processing dependencies. Example: a customer request involves an update to 3 tables in a database. For this update to be atomic, all 3 transaction updates should happen or nothing at all. Contract Coupling → data transfer level: data exchange between microservices should agree on the data format being exchange (JSON schema, XML schema, RPC, etc). More details on Managing Contracts section below. Temporal Coupling → availability of the interacting microservices. Example: microservice A requires microservice B to be available at a specific time to perform some functionality. The Three Primal Dynamic-Coupling Forces Every distributed system is shaped by three fundamental tensions: Each of these forces is acting in their own spectrum axis which combine to form the 8 saga patterns covered later in Section 4. Force Options Impact on Distributed System Characteristics Communication Synchronous ↔ Asynchronous ★★ Consistency Atomic ↔ Eventual ★★★ Coordination Orchestration ↔ Choreography ★ The impacts of each of these driving forces will become apparent when we compare 8 different types of sagas based on the permutation of the options. 1. Communication Synchronous vs. Asynchronous Synchronous Asynchronous Tasks run in order Tasks run independently Often blocking the thread Using callbacks for completion Blocking vs. Non-blocking Subtle difference between synchronous/asynchronous and blocking/non-blocking: Synchronous/Asynchronous Blocking/Non-blocking On a system level On a thread level Relates to when a task finishes and how the result is handled (flow control) Relates to whether the thread is suspended while waiting for a task (resource state) Examples Synchronous &amp; Blocking (Standard): You call a function, and your code stops (blocks) and waits for the result before moving to the next line. Example: Reading a large file from disk; the program pauses until the file is fully loaded. Synchronous &amp; Non-blocking: You start a task and immediately get control back (non-blocking), but you must manually check back (polling) until the task is complete. Example: Starting a download, then checking the progress bar every few seconds, but you still wait for that specific download to finish to proceed. Asynchronous &amp; Blocking (Rare/Inefficient): The task runs in the background (asynchronous), but you still stop and wait for it to finish. Example: Starting a background task, but immediately sitting idle waiting for the “done” notification. Asynchronous &amp; Non-blocking (Modern): You start a task and immediately move on to other work (non-blocking). When the task finishes, you are notified (asynchronous). Example: Sending an API request with a callback function; the main thread continues executing other code and handles the result only when the request completes. Architectural Quantum An architecture quantum establishes the scope for a set of architectural characteristics. Characteristics of a quantum: Independent deployment High functional cohesion Low external-implementation static coupling Synchronous communication with other quanta Synchronous calls create “dynamic quantum entanglement” — they couple the operational characteristics of separate services. A slow or unavailable downstream service degrades the entire call chain, i.e. the weakest characteristic of a service becomes the characteristic of the system. **Your system is only as good as the least characteristics ** Asynchronous calls, on the other hand, retains the architecture quantum of individual services in a system. Example: In the above picture, the microservices on the right side form 1 architectural quanta because of the synchronous communication among the services. When Portfolio Management System communicates with Trade Order Orchestrator, 2 things can happen: If they communicate synchronously, they form into 1 architectural quantum =&gt; architectural characteristics drop to the lower level in the workflow. If they communicate asynchronously, they stay separated as 2 architectural quanta =&gt; architectural characteristics are retained. So how do we determine the communication type should be synchronous or asynchronous? It depends on whether the service needs to wait for the response from another service. If so, then it’s synchronous. Also for simplicity, default to synchronous communication. Synchronous → simpler Trade-off Summary   Synchronous Asynchronous Easy to reason about ✅   Mimics non-distributed calls ✅   Easier to implement ✅   Highly decoupled   ✅ High performance and scale   ✅ Common performance tuning technique   ✅ Performance impact on interactive systems ⚠️   Creates dynamic quantum entanglements ⚠️   Complex to build and debug   ⚠️ Difficult for transactional behaviour   ⚠️ Complex error handling   ⚠️ Managing Contracts When a service calls a method in another service, it’s a contract between the 2 services of what the request and response formats should be like. Strict vs. Loose Contracts   Tight (Strict) Loose Guaranteed contract fidelity ✅   Build-time validation ✅   Better for decoupled architectures   ✅ Easier to evolve   ✅ Decouples integration from implementation platform   ✅ Brittle integration points ⚠️   Requires versioning ⚠️   Less certainty; needs fitness functions   ⚠️ Requires developer discipline   ⚠️ Principle: Transfer values, not types. Value-based (loose) contracts decouple consumers from implementation changes. Contract Fitness Functions Consumer-Driven Contracts (CDCs) can automate contract verification. The Pact framework (docs.pact.io) supports this for REST and event-driven architectures, with CI/CD integration. Event Payload Design Should an event carry the full data payload or just key identifiers? Trade-off Dimension Full Payload Key-Only Payload Scalability &amp; performance ✅ Good ⚠️ Poor Contract management &amp; versioning ⚠️ Complex ✅ Simple Single system of record ⚠️ Multiple ✅ Single Stamp coupling &amp; bandwidth ⚠️ High ✅ Low Choose Key-Only Payload if scalability and performance are not the priority Stamp coupling example: A customer profile returning 500 KB payloads at 2,000 req/s uses ~1,000,000 KB/s of bandwidth. Returning only required fields (~200 bytes) reduces this to ~400 KB/s — a 2,500× reduction. Looser contracts create less brittle software architectures. 2. Coordination Orchestration vs. Choreography Orchestration generally one orchestrator per major workflow orchestrator owns state and communicates update points to services Choreography services react to events no central controller the workflow emerges from the chain of events Hybrids an orchestrated outer workflow can delegate to choreographed sub-workflows Summary   Orchestration Choreography State owner Central orchestrator Distributed across services Workflow control Centralised → tighter coupling Emergent / event-driven → loose coupling Error handling ✅ Easier — one place ⚠️ Harder — spread across services Responsiveness Moderate ✅ High Scalability / throughput Moderate ✅ High Fault tolerance ✅ Good ✅ Better Recoverability ✅ Good ⚠️ Difficult Workflow / state management ✅ Good ⚠️ Complex 3. Consistency ACID Transactions Atomicity — all steps in a transaction either fully succeed or fully roll back together; there is no partial completion. Consistency — a transaction always moves the database from one valid state to another, never leaving data in a corrupt or rule-violating state. Isolation — concurrent transactions are invisible to each other until committed, so one transaction cannot see another’s in-progress changes. Durability — once a transaction is committed, the data is permanently saved and survives any subsequent system failure. In a distributed context, standard ACID properties break down: Property Problem in Distributed Systems Atomicity Each service commits/rolls back independently — a failure mid-chain leaves partial state Consistency An error in one service (e.g. inventory) causes data inconsistency across others Isolation Inserted data may be visible to other services before the overall transaction completes Durability Data is only made permanent at the service level, not the transaction level BASE Transactions As an alternative, BASE (Basically Available, Soft state, Eventually consistent) is the natural fit for distributed, decoupled systems. Eventual Consistency Patterns Sample problem: Deleting a customer in one service must propagate to dependent services (wish list, preferences, etc.). 3 patterns for propagating state changes from the sample above: Background Synchronisation → a background job reads across databases to sync state. ⚠️ Creates direct database coupling between services. Event-Based Data Synchronisation → the originating service fires an event; consumers react. ✅ Decoupled. Standard Event-Driven Architecture pattern. Workflow Event Pattern → a dedicated workflow processor mediates between the event producer and consumers, handling ordering and retries. Compensating Updates When a step fails partway through a distributed transaction, previously committed changes must be compensated (rolled back manually). Fallacies of compensating updates: The compensating update itself may fail Side effects may have already occurred (e.g. an email sent, a charge processed) State management becomes complex Mitigation (by state management): Marking data as WIP (Work-In-Progress) vs PLACED allows services to avoid querying data not yet in a finalisable state, reducing inconsistency windows. When a system incorporates process for compensating updates, execution logs is crucial for traceability. 4. Transactional Sagas 8 Saga patterns can be formed by combining the 3 coupling forces: Saga Consistency Coordination Communication Epic Saga Atomic Orchestration Sync Fantasy Fiction Saga Atomic Orchestration Async Phone Tag Saga Atomic Choreography Sync Horror Story Saga Atomic Choreography Async Fairy Tale Saga Eventual Orchestration Sync Parallel Saga Eventual Orchestration Async Time Travel Saga Eventual Choreography Sync Anthology Saga Eventual Choreography Async Saga Descriptions 🗡️ Epic Saga — “A long-running, heroic story” Mimics a non-distributed transactional interaction Holistic transactional coordination increases coupling Easy to understand; difficult to implement Use when: Each step must complete before the next starts; absolute transactionality matters more than responsiveness. 📖 Fantasy Fiction Saga — “A complex story that’s hard to believe in the end” Moving to async communication improves performance/responsiveness… …but introduces concurrency issues that may be worse than the original performance problems Use when: A first attempt at improving an Epic Saga; responsiveness matters more than strict ordering. 🏡 Fairy Tale Saga — “An easy story with a pleasant ending” Sync + orchestrated = easiest to reason about The Orchestrated Saga in Chris Richardson’s Microservices Patterns book Use when: Medium to complex workflows that don’t need extreme scale. Default choice for most situations. ⚡ Parallel Saga — “Multiple stories running at the same time” Orchestrator allows complex workflows with concurrency Highly attractive for complex workflows at high scale Difficult if ordering of updates matters 📞 Phone Tag Saga — “Like the game of phone tag” An unusual combination: atomic + choreography Adds scalability to a simple transactional workflow when the orchestrator becomes a bottleneck Not common in practice 😱 Horror Story Saga — “A nightmare” Attempts atomic workflows without a coordinator, with concurrency on top Workflow, error handling, boundary conditions, and transactionality are spread across domain services Middling performance coupled with impossible-to-reproduce errors Actually an anti-pattern ⚠️ Not uncommon in practice. Usually a well-intentioned but flawed attempt to achieve high performance with atomicity. ⏳ Time Travel Saga — “A problem that moves atomically through time” No orchestrator makes complex workflows difficult Best for pipeline problems (chain-of-responsibility, pipes-and-filters) with staging or additive workflows Works best when synchronous communication is acceptable 📚 Anthology Saga — “A loosely associated group of short stories” The Choreographed Saga in Chris Richardson’s Microservices Patterns book Polar opposite of the Epic Saga Best for non-transactional pipes-and-filters architecture styles Highly scalable due to lack of coupling - the least coupled option Quantitative Trade-off Summary Mixing the properties of the 3 axes of dynamic coupling forces, Consistency choice has the greatest impact on saga quality, followed by Coordination style then Communication mode. Consistency → Coordination → Communication Axis Impact on Decoupling / Scalability Consistency: Atomic → Eventual +163% improvement Coordination: Orchestration → Choreography +143% improvement Communcation: Sync → Async +55% improvement Saga Profiles Below is the 8 transactional sagas score cards: The table above gives a simplified guidance on the system architecture we should have to achieve the characteristic priorities implied. For example, to have a distributed system with low response latency, the table shows below: Now the option is just either we want orchestrated or choreographed system. If scalability is the next priority, then anthology saga is the pattern we should follow. If simplicity is, parallel saga is the pattern. Also from the table we can see that what drives an orchestration system down on scalability and responsiveness is not the orchestration itself but it’s the atomic transactions. Once we tweak the transactions to be eventual consistent, we should expect improvements in responsiveness and scalability of the system. Transactional Sharding For very high-volume scenarios, domain sharding distributes load across multiple Saga instances for better performance/responsiveness. Example: a concert ticket sale spike can be handled by sharding by seat section or venue zone, avoiding a single transaction bottleneck. Domain sharding maps naturally onto microservices: services can be sharded by geography or specialisation, allowing concurrent saga instances without contention. Key Principles Summary Principle Implication Synchronous calls create dynamic quantum entanglement Default to async where responsiveness and scale matter Looser contracts = less brittle software Prefer value-based contracts in microservices Stamp coupling wastes bandwidth Send only the data a consumer needs ACID breaks in distributed systems Accept eventual consistency where business rules allow Compensating updates have fallacies Use state management to reduce inconsistency windows Fairy Tale Saga is the default Use it for most medium-complexity workflows Horror Story Saga is an antipattern Avoid atomic + choreography + async Anthology Saga is the most scalable Use for pipelines that don’t require transactionality]]></summary></entry><entry><title type="html">Java 25 – New Features Overview</title><link href="http://www.javarchitect.com/java25-features/" rel="alternate" type="text/html" title="Java 25 – New Features Overview" /><published>2026-03-16T00:00:00+00:00</published><updated>2026-03-16T00:00:00+00:00</updated><id>http://www.javarchitect.com/java25-features</id><content type="html" xml:base="http://www.javarchitect.com/java25-features/"><![CDATA[<p>Java 25 (JDK 25) introduces improvements across the Java language,
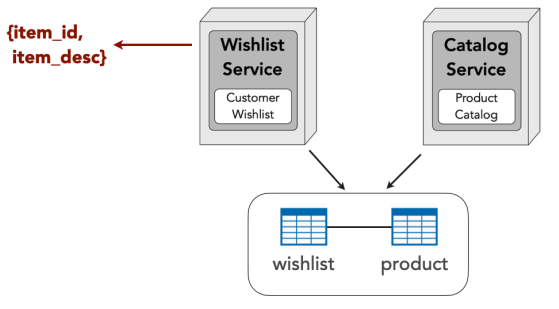
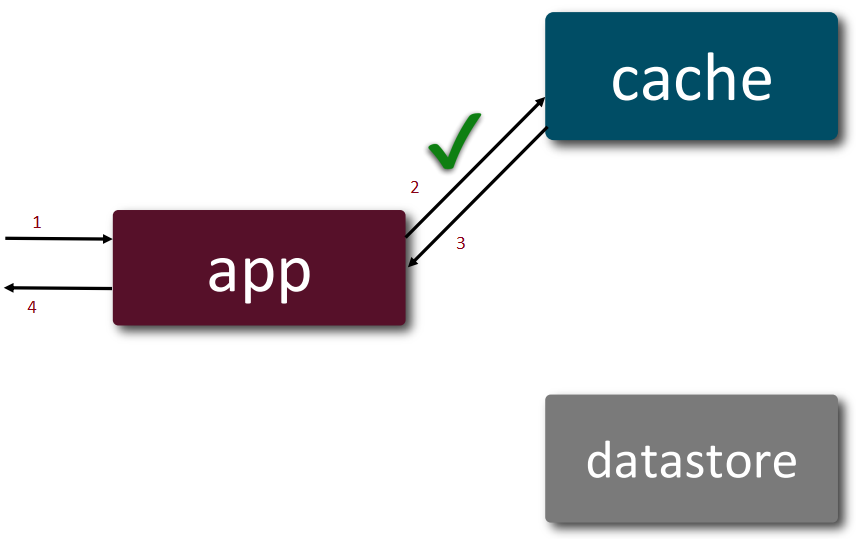
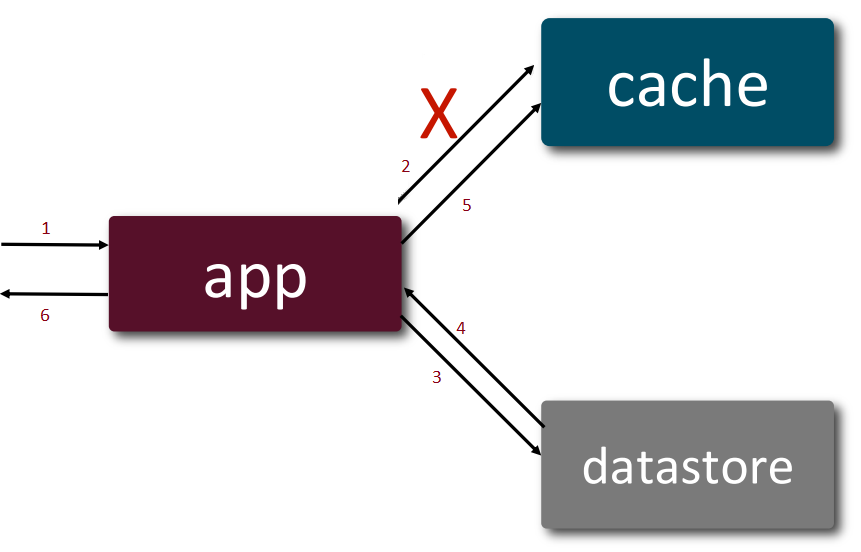
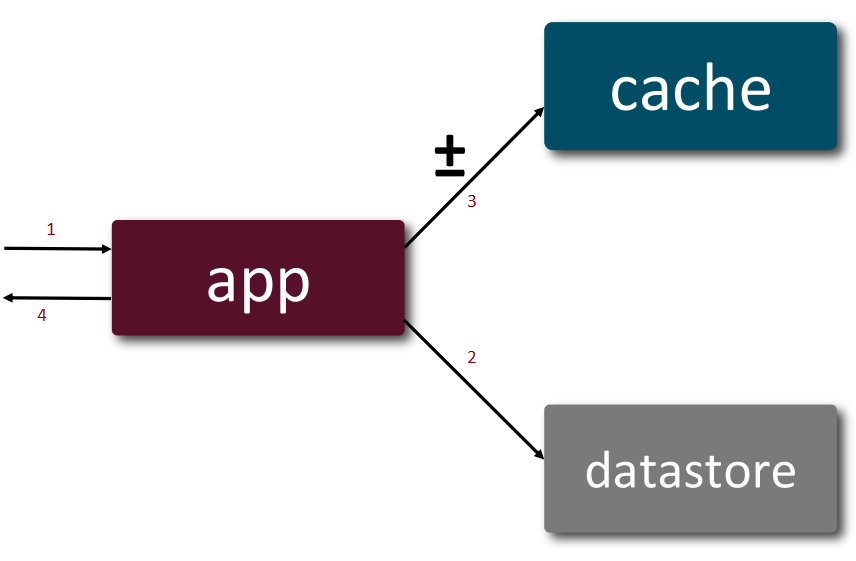
runtime performance, concurrency model, security APIs, and observability
tooling.</p>

<p>This document summarizes the most important updates relevant for
developers.</p>

<hr />

<h1 id="1-language-features">1. Language Features</h1>

<h2 id="primitive-types-in-pattern-matching-preview">Primitive Types in Pattern Matching (Preview)</h2>

<p>Pattern matching has been expanded to support primitive types in
<code class="language-plaintext highlighter-rouge">switch</code> and other pattern contexts.</p>

<p>Example:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">switch</span> <span class="o">(</span><span class="n">value</span><span class="o">)</span> <span class="o">{</span>
    <span class="k">case</span> <span class="kt">int</span> <span class="n">i</span> <span class="o">-&gt;</span> <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Integer: "</span> <span class="o">+</span> <span class="n">i</span><span class="o">);</span>
    <span class="k">case</span> <span class="kt">double</span> <span class="n">d</span> <span class="o">-&gt;</span> <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Double: "</span> <span class="o">+</span> <span class="n">d</span><span class="o">);</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Benefits:</p>

<ul>
  <li>More consistent pattern matching</li>
  <li>Simplifies conditional logic</li>
  <li>Better support for performance‑sensitive code</li>
</ul>

<hr />

<h2 id="module-import-declarations">Module Import Declarations</h2>

<p>Java now allows importing all exported packages from a module in a
single statement.</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">module</span> <span class="n">java</span><span class="o">.</span><span class="na">sql</span><span class="o">;</span>
</code></pre></div></div>

<p>Advantages:</p>

<ul>
  <li>Reduces boilerplate imports</li>
  <li>Makes modular libraries easier to use</li>
  <li>Simplifies dependency usage</li>
</ul>

<hr />

<h2 id="compact-source-files-and-instance-main-methods">Compact Source Files and Instance Main Methods</h2>

<p>This feature removes much of the boilerplate needed for small programs.</p>

<p>Traditional Java:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">class</span> <span class="nc">Hello</span> <span class="o">{</span>
    <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
        <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Hello World"</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Simplified version:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kt">void</span> <span class="nf">main</span><span class="o">()</span> <span class="o">{</span>
    <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"Hello World"</span><span class="o">);</span>
<span class="o">}</span>
</code></pre></div></div>

<hr />

<h1 id="2-concurrency-improvements">2. Concurrency Improvements</h1>

<h2 id="structured-concurrency">Structured Concurrency</h2>

<p>Structured concurrency simplifies working with groups of concurrent
tasks.</p>

<p>Concept example:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">try</span> <span class="o">(</span><span class="kt">var</span> <span class="n">scope</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">StructuredTaskScope</span><span class="o">.</span><span class="na">ShutdownOnFailure</span><span class="o">())</span> <span class="o">{</span>
    <span class="nc">Future</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">&gt;</span> <span class="n">user</span> <span class="o">=</span> <span class="n">scope</span><span class="o">.</span><span class="na">fork</span><span class="o">(()</span> <span class="o">-&gt;</span> <span class="n">findUser</span><span class="o">());</span>
    <span class="nc">Future</span><span class="o">&lt;</span><span class="nc">Integer</span><span class="o">&gt;</span> <span class="n">order</span> <span class="o">=</span> <span class="n">scope</span><span class="o">.</span><span class="na">fork</span><span class="o">(()</span> <span class="o">-&gt;</span> <span class="n">fetchOrder</span><span class="o">());</span>

    <span class="n">scope</span><span class="o">.</span><span class="na">join</span><span class="o">();</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Benefits:</p>

<ul>
  <li>Simplified thread coordination</li>
  <li>Improved error handling</li>
  <li>Better cancellation support</li>
</ul>

<hr />

<h2 id="scoped-values">Scoped Values</h2>

<p>Scoped values provide a safe alternative to <code class="language-plaintext highlighter-rouge">ThreadLocal</code> variables.</p>

<p>Key characteristics:</p>

<ul>
  <li>Immutable data sharing</li>
  <li>Lower memory overhead</li>
  <li>Better integration with virtual threads</li>
</ul>

<p>Example:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nc">ScopedValue</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">&gt;</span> <span class="no">USER</span> <span class="o">=</span> <span class="nc">ScopedValue</span><span class="o">.</span><span class="na">newInstance</span><span class="o">();</span>
</code></pre></div></div>

<hr />

<h1 id="3-performance-improvements">3. Performance Improvements</h1>

<h2 id="compact-object-headers">Compact Object Headers</h2>

<p>Java 25 introduces smaller object headers on 64‑bit architectures.</p>

<p>Benefits:</p>

<ul>
  <li>Reduced memory footprint</li>
  <li>Improved cache efficiency</li>
  <li>Higher application density</li>
</ul>

<hr />

<h2 id="vector-api">Vector API</h2>

<p>The Vector API allows developers to write vectorized computations that
map to modern CPU vector instructions.</p>

<p>Use cases:</p>

<ul>
  <li>machine learning</li>
  <li>financial simulations</li>
  <li>scientific computing</li>
  <li>AI inference workloads</li>
</ul>

<hr />

<h1 id="4-security-enhancements">4. Security Enhancements</h1>

<h2 id="pem-encoding-api">PEM Encoding API</h2>

<p>Java introduces a built-in API for reading and writing cryptographic
objects in PEM format.</p>

<p>Supported items include:</p>

<ul>
  <li>cryptographic keys</li>
  <li>certificates</li>
  <li>certificate revocation lists</li>
</ul>

<hr />

<h2 id="key-derivation-function-api">Key Derivation Function API</h2>

<p>Provides standard APIs for deriving secure cryptographic keys from
shared secrets.</p>

<p>Use cases:</p>

<ul>
  <li>encryption systems</li>
  <li>password-based key generation</li>
  <li>modern cryptographic protocols</li>
</ul>

<hr />

<h1 id="5-observability-improvements">5. Observability Improvements</h1>

<h2 id="java-flight-recorder-enhancements">Java Flight Recorder Enhancements</h2>

<p>Java Flight Recorder receives improvements including:</p>

<ul>
  <li>CPU-time profiling</li>
  <li>cooperative stack sampling</li>
  <li>detailed method timing</li>
</ul>

<p>These tools improve diagnostics for performance bottlenecks in
production systems.</p>

<hr />

<h1 id="6-platform-changes">6. Platform Changes</h1>

<h2 id="removal-of-32bit-x86-support">Removal of 32‑bit x86 Support</h2>

<p>Java 25 removes support for legacy 32‑bit x86 systems, focusing
exclusively on modern 64‑bit architectures.</p>

<p>Benefits:</p>

<ul>
  <li>simplified JVM maintenance</li>
  <li>better performance optimizations</li>
  <li>reduced platform complexity</li>
</ul>

<hr />

<h1 id="conclusion">Conclusion</h1>

<p>Java 25 continues improving the platform with stronger support for:</p>

<ul>
  <li>concurrency</li>
  <li>performance optimization</li>
  <li>cryptography</li>
  <li>developer productivity</li>
  <li>runtime observability</li>
</ul>

<p>These improvements help keep Java competitive for enterprise systems,
cloud workloads, and high-performance computing.</p>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[Java 25 (JDK 25) introduces improvements across the Java language, runtime performance, concurrency model, security APIs, and observability tooling. This document summarizes the most important updates relevant for developers. 1. Language Features Primitive Types in Pattern Matching (Preview) Pattern matching has been expanded to support primitive types in switch and other pattern contexts. Example: switch (value) { case int i -&gt; System.out.println("Integer: " + i); case double d -&gt; System.out.println("Double: " + d); } Benefits: More consistent pattern matching Simplifies conditional logic Better support for performance‑sensitive code Module Import Declarations Java now allows importing all exported packages from a module in a single statement. import module java.sql; Advantages: Reduces boilerplate imports Makes modular libraries easier to use Simplifies dependency usage Compact Source Files and Instance Main Methods This feature removes much of the boilerplate needed for small programs. Traditional Java: public class Hello { public static void main(String[] args) { System.out.println("Hello World"); } } Simplified version: void main() { System.out.println("Hello World"); } 2. Concurrency Improvements Structured Concurrency Structured concurrency simplifies working with groups of concurrent tasks. Concept example: try (var scope = new StructuredTaskScope.ShutdownOnFailure()) { Future&lt;String&gt; user = scope.fork(() -&gt; findUser()); Future&lt;Integer&gt; order = scope.fork(() -&gt; fetchOrder()); scope.join(); } Benefits: Simplified thread coordination Improved error handling Better cancellation support Scoped Values Scoped values provide a safe alternative to ThreadLocal variables. Key characteristics: Immutable data sharing Lower memory overhead Better integration with virtual threads Example: ScopedValue&lt;String&gt; USER = ScopedValue.newInstance(); 3. Performance Improvements Compact Object Headers Java 25 introduces smaller object headers on 64‑bit architectures. Benefits: Reduced memory footprint Improved cache efficiency Higher application density Vector API The Vector API allows developers to write vectorized computations that map to modern CPU vector instructions. Use cases: machine learning financial simulations scientific computing AI inference workloads 4. Security Enhancements PEM Encoding API Java introduces a built-in API for reading and writing cryptographic objects in PEM format. Supported items include: cryptographic keys certificates certificate revocation lists Key Derivation Function API Provides standard APIs for deriving secure cryptographic keys from shared secrets. Use cases: encryption systems password-based key generation modern cryptographic protocols 5. Observability Improvements Java Flight Recorder Enhancements Java Flight Recorder receives improvements including: CPU-time profiling cooperative stack sampling detailed method timing These tools improve diagnostics for performance bottlenecks in production systems. 6. Platform Changes Removal of 32‑bit x86 Support Java 25 removes support for legacy 32‑bit x86 systems, focusing exclusively on modern 64‑bit architectures. Benefits: simplified JVM maintenance better performance optimizations reduced platform complexity Conclusion Java 25 continues improving the platform with stronger support for: concurrency performance optimization cryptography developer productivity runtime observability These improvements help keep Java competitive for enterprise systems, cloud workloads, and high-performance computing.]]></summary></entry><entry><title type="html">Hexagonal Architecture in Java: A Simple Implementation with Multiple Ports</title><link href="http://www.javarchitect.com/hexagonal-architecture-simple-sample/" rel="alternate" type="text/html" title="Hexagonal Architecture in Java: A Simple Implementation with Multiple Ports" /><published>2025-09-16T00:00:00+00:00</published><updated>2025-09-16T00:00:00+00:00</updated><id>http://www.javarchitect.com/hexagonal-architecture-simple-sample</id><content type="html" xml:base="http://www.javarchitect.com/hexagonal-architecture-simple-sample/"><![CDATA[<p>Hexagonal Architecture, also known as <strong>Ports and Adapters</strong>, is a software architectural style introduced by Alistair Cockburn. Its goal is to isolate the <strong>core business logic</strong> from external systems — such as databases, message brokers, or user interfaces — by putting them behind well-defined <strong>ports</strong> and implementing them through <strong>adapters</strong>.</p>

<p>This decoupling brings versatility: the same domain logic can interact with different clients and persistence mechanisms without modification.</p>

<hr />

<h2 id="why-hexagonal-architecture">Why Hexagonal Architecture?</h2>

<p>In a traditional layered architecture, the domain model often leaks dependencies on persistence or UI layers. For example, switching from a REST API to a CLI or from a relational database to an in-memory store can require changes to the business code.</p>

<p>Hexagonal architecture solves this by:</p>

<ul>
  <li><strong>Defining input ports</strong>: how external actors (users, APIs, scheduled jobs) communicate with the application.</li>
  <li><strong>Defining output ports</strong>: how the application communicates with external systems (databases, queues, external services).</li>
  <li><strong>Keeping the core domain pure</strong>: the business logic depends only on ports, not on specific technologies.</li>
</ul>

<hr />

<h2 id="example-scenario">Example Scenario</h2>

<p>Let’s implement a simple <strong>Task Management</strong> system with:</p>

<ul>
  <li>
    <p><strong>2 Input Ports</strong>:</p>

    <ol>
      <li>A REST API (adapter).</li>
      <li>A Command-Line Interface (adapter).</li>
    </ol>
  </li>
  <li>
    <p><strong>2 Output Ports</strong>:</p>

    <ol>
      <li>A persistence store (adapter for in-memory or database).</li>
      <li>A notification service (adapter for console logging or email).</li>
    </ol>
  </li>
</ul>

<p>The core domain logic only knows about ports, not about HTTP, JDBC, or logging.</p>

<hr />

<h2 id="step-1-define-the-domain-model">Step 1: Define the Domain Model</h2>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">class</span> <span class="nc">Task</span> <span class="o">{</span>
    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">String</span> <span class="n">id</span><span class="o">;</span>
    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">String</span> <span class="n">description</span><span class="o">;</span>
    <span class="kd">private</span> <span class="kt">boolean</span> <span class="n">completed</span><span class="o">;</span>

    <span class="kd">public</span> <span class="nf">Task</span><span class="o">(</span><span class="nc">String</span> <span class="n">id</span><span class="o">,</span> <span class="nc">String</span> <span class="n">description</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">this</span><span class="o">.</span><span class="na">id</span> <span class="o">=</span> <span class="n">id</span><span class="o">;</span>
        <span class="k">this</span><span class="o">.</span><span class="na">description</span> <span class="o">=</span> <span class="n">description</span><span class="o">;</span>
        <span class="k">this</span><span class="o">.</span><span class="na">completed</span> <span class="o">=</span> <span class="kc">false</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="kd">public</span> <span class="kt">void</span> <span class="nf">markCompleted</span><span class="o">()</span> <span class="o">{</span>
        <span class="k">this</span><span class="o">.</span><span class="na">completed</span> <span class="o">=</span> <span class="kc">true</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="kd">public</span> <span class="kt">boolean</span> <span class="nf">isCompleted</span><span class="o">()</span> <span class="o">{</span>
        <span class="k">return</span> <span class="n">completed</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="kd">public</span> <span class="nc">String</span> <span class="nf">getId</span><span class="o">()</span> <span class="o">{</span>
        <span class="k">return</span> <span class="n">id</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="kd">public</span> <span class="nc">String</span> <span class="nf">getDescription</span><span class="o">()</span> <span class="o">{</span>
        <span class="k">return</span> <span class="n">description</span><span class="o">;</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<hr />

<h2 id="step-2-define-ports">Step 2: Define Ports</h2>

<h3 id="input-ports-driving-the-application">Input Ports (driving the application)</h3>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">interface</span> <span class="nc">TaskUseCase</span> <span class="o">{</span>
    <span class="nc">Task</span> <span class="nf">createTask</span><span class="o">(</span><span class="nc">String</span> <span class="n">description</span><span class="o">);</span>
    <span class="kt">void</span> <span class="nf">completeTask</span><span class="o">(</span><span class="nc">String</span> <span class="n">taskId</span><span class="o">);</span>
<span class="o">}</span>
</code></pre></div></div>

<h3 id="output-ports-driven-by-the-application">Output Ports (driven by the application)</h3>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">interface</span> <span class="nc">TaskRepository</span> <span class="o">{</span>
    <span class="nc">Task</span> <span class="nf">save</span><span class="o">(</span><span class="nc">Task</span> <span class="n">task</span><span class="o">);</span>
    <span class="nc">Task</span> <span class="nf">findById</span><span class="o">(</span><span class="nc">String</span> <span class="n">id</span><span class="o">);</span>
<span class="o">}</span>

<span class="kd">public</span> <span class="kd">interface</span> <span class="nc">NotificationService</span> <span class="o">{</span>
    <span class="kt">void</span> <span class="nf">notify</span><span class="o">(</span><span class="nc">String</span> <span class="n">message</span><span class="o">);</span>
<span class="o">}</span>
</code></pre></div></div>

<hr />

<h2 id="step-3-core-application-logic">Step 3: Core Application Logic</h2>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">java.util.UUID</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">class</span> <span class="nc">TaskService</span> <span class="kd">implements</span> <span class="nc">TaskUseCase</span> <span class="o">{</span>

    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">TaskRepository</span> <span class="n">taskRepository</span><span class="o">;</span>
    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">NotificationService</span> <span class="n">notificationService</span><span class="o">;</span>

    <span class="kd">public</span> <span class="nf">TaskService</span><span class="o">(</span><span class="nc">TaskRepository</span> <span class="n">taskRepository</span><span class="o">,</span> <span class="nc">NotificationService</span> <span class="n">notificationService</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">this</span><span class="o">.</span><span class="na">taskRepository</span> <span class="o">=</span> <span class="n">taskRepository</span><span class="o">;</span>
        <span class="k">this</span><span class="o">.</span><span class="na">notificationService</span> <span class="o">=</span> <span class="n">notificationService</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="nd">@Override</span>
    <span class="kd">public</span> <span class="nc">Task</span> <span class="nf">createTask</span><span class="o">(</span><span class="nc">String</span> <span class="n">description</span><span class="o">)</span> <span class="o">{</span>
        <span class="nc">Task</span> <span class="n">task</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">Task</span><span class="o">(</span><span class="no">UUID</span><span class="o">.</span><span class="na">randomUUID</span><span class="o">().</span><span class="na">toString</span><span class="o">(),</span> <span class="n">description</span><span class="o">);</span>
        <span class="n">taskRepository</span><span class="o">.</span><span class="na">save</span><span class="o">(</span><span class="n">task</span><span class="o">);</span>
        <span class="n">notificationService</span><span class="o">.</span><span class="na">notify</span><span class="o">(</span><span class="s">"Task created: "</span> <span class="o">+</span> <span class="n">task</span><span class="o">.</span><span class="na">getDescription</span><span class="o">());</span>
        <span class="k">return</span> <span class="n">task</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="nd">@Override</span>
    <span class="kd">public</span> <span class="kt">void</span> <span class="nf">completeTask</span><span class="o">(</span><span class="nc">String</span> <span class="n">taskId</span><span class="o">)</span> <span class="o">{</span>
        <span class="nc">Task</span> <span class="n">task</span> <span class="o">=</span> <span class="n">taskRepository</span><span class="o">.</span><span class="na">findById</span><span class="o">(</span><span class="n">taskId</span><span class="o">);</span>
        <span class="n">task</span><span class="o">.</span><span class="na">markCompleted</span><span class="o">();</span>
        <span class="n">taskRepository</span><span class="o">.</span><span class="na">save</span><span class="o">(</span><span class="n">task</span><span class="o">);</span>
        <span class="n">notificationService</span><span class="o">.</span><span class="na">notify</span><span class="o">(</span><span class="s">"Task completed: "</span> <span class="o">+</span> <span class="n">task</span><span class="o">.</span><span class="na">getDescription</span><span class="o">());</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Notice that <code class="language-plaintext highlighter-rouge">TaskService</code> doesn’t know if persistence is a database or in-memory, or if notifications go to email, SMS, or console.</p>

<hr />

<h2 id="step-4-implement-adapters">Step 4: Implement Adapters</h2>

<h3 id="output-adapters">Output Adapters</h3>

<p>In-memory persistence:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">java.util.HashMap</span><span class="o">;</span>
<span class="kn">import</span> <span class="nn">java.util.Map</span><span class="o">;</span>

<span class="kd">public</span> <span class="kd">class</span> <span class="nc">InMemoryTaskRepository</span> <span class="kd">implements</span> <span class="nc">TaskRepository</span> <span class="o">{</span>
    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">Map</span><span class="o">&lt;</span><span class="nc">String</span><span class="o">,</span> <span class="nc">Task</span><span class="o">&gt;</span> <span class="n">store</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">HashMap</span><span class="o">&lt;&gt;();</span>

    <span class="nd">@Override</span>
    <span class="kd">public</span> <span class="nc">Task</span> <span class="nf">save</span><span class="o">(</span><span class="nc">Task</span> <span class="n">task</span><span class="o">)</span> <span class="o">{</span>
        <span class="n">store</span><span class="o">.</span><span class="na">put</span><span class="o">(</span><span class="n">task</span><span class="o">.</span><span class="na">getId</span><span class="o">(),</span> <span class="n">task</span><span class="o">);</span>
        <span class="k">return</span> <span class="n">task</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="nd">@Override</span>
    <span class="kd">public</span> <span class="nc">Task</span> <span class="nf">findById</span><span class="o">(</span><span class="nc">String</span> <span class="n">id</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">return</span> <span class="n">store</span><span class="o">.</span><span class="na">get</span><span class="o">(</span><span class="n">id</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>Console notification:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">class</span> <span class="nc">ConsoleNotificationService</span> <span class="kd">implements</span> <span class="nc">NotificationService</span> <span class="o">{</span>
    <span class="nd">@Override</span>
    <span class="kd">public</span> <span class="kt">void</span> <span class="nf">notify</span><span class="o">(</span><span class="nc">String</span> <span class="n">message</span><span class="o">)</span> <span class="o">{</span>
        <span class="nc">System</span><span class="o">.</span><span class="na">out</span><span class="o">.</span><span class="na">println</span><span class="o">(</span><span class="s">"NOTIFICATION: "</span> <span class="o">+</span> <span class="n">message</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<h3 id="input-adapters">Input Adapters</h3>

<p>Command-line interface:</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">class</span> <span class="nc">CliAdapter</span> <span class="o">{</span>
    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">TaskUseCase</span> <span class="n">taskUseCase</span><span class="o">;</span>

    <span class="kd">public</span> <span class="nf">CliAdapter</span><span class="o">(</span><span class="nc">TaskUseCase</span> <span class="n">taskUseCase</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">this</span><span class="o">.</span><span class="na">taskUseCase</span> <span class="o">=</span> <span class="n">taskUseCase</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="kd">public</span> <span class="kt">void</span> <span class="nf">run</span><span class="o">()</span> <span class="o">{</span>
        <span class="nc">Task</span> <span class="n">task</span> <span class="o">=</span> <span class="n">taskUseCase</span><span class="o">.</span><span class="na">createTask</span><span class="o">(</span><span class="s">"Write hexagonal architecture article"</span><span class="o">);</span>
        <span class="n">taskUseCase</span><span class="o">.</span><span class="na">completeTask</span><span class="o">(</span><span class="n">task</span><span class="o">.</span><span class="na">getId</span><span class="o">());</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<p>REST controller (example using Spring Web):</p>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kn">import</span> <span class="nn">org.springframework.web.bind.annotation.*</span><span class="o">;</span>

<span class="nd">@RestController</span>
<span class="nd">@RequestMapping</span><span class="o">(</span><span class="s">"/tasks"</span><span class="o">)</span>
<span class="kd">public</span> <span class="kd">class</span> <span class="nc">RestAdapter</span> <span class="o">{</span>

    <span class="kd">private</span> <span class="kd">final</span> <span class="nc">TaskUseCase</span> <span class="n">taskUseCase</span><span class="o">;</span>

    <span class="kd">public</span> <span class="nf">RestAdapter</span><span class="o">(</span><span class="nc">TaskUseCase</span> <span class="n">taskUseCase</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">this</span><span class="o">.</span><span class="na">taskUseCase</span> <span class="o">=</span> <span class="n">taskUseCase</span><span class="o">;</span>
    <span class="o">}</span>

    <span class="nd">@PostMapping</span>
    <span class="kd">public</span> <span class="nc">Task</span> <span class="nf">create</span><span class="o">(</span><span class="nd">@RequestParam</span> <span class="nc">String</span> <span class="n">description</span><span class="o">)</span> <span class="o">{</span>
        <span class="k">return</span> <span class="n">taskUseCase</span><span class="o">.</span><span class="na">createTask</span><span class="o">(</span><span class="n">description</span><span class="o">);</span>
    <span class="o">}</span>

    <span class="nd">@PostMapping</span><span class="o">(</span><span class="s">"/{id}/complete"</span><span class="o">)</span>
    <span class="kd">public</span> <span class="kt">void</span> <span class="nf">complete</span><span class="o">(</span><span class="nd">@PathVariable</span> <span class="nc">String</span> <span class="n">id</span><span class="o">)</span> <span class="o">{</span>
        <span class="n">taskUseCase</span><span class="o">.</span><span class="na">completeTask</span><span class="o">(</span><span class="n">id</span><span class="o">);</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<hr />

<h2 id="step-5-wiring-it-together">Step 5: Wiring It Together</h2>

<div class="language-java highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="kd">public</span> <span class="kd">class</span> <span class="nc">Application</span> <span class="o">{</span>
    <span class="kd">public</span> <span class="kd">static</span> <span class="kt">void</span> <span class="nf">main</span><span class="o">(</span><span class="nc">String</span><span class="o">[]</span> <span class="n">args</span><span class="o">)</span> <span class="o">{</span>
        <span class="nc">TaskRepository</span> <span class="n">repository</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">InMemoryTaskRepository</span><span class="o">();</span>
        <span class="nc">NotificationService</span> <span class="n">notification</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">ConsoleNotificationService</span><span class="o">();</span>
        <span class="nc">TaskUseCase</span> <span class="n">taskService</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">TaskService</span><span class="o">(</span><span class="n">repository</span><span class="o">,</span> <span class="n">notification</span><span class="o">);</span>

        <span class="c1">// CLI example</span>
        <span class="nc">CliAdapter</span> <span class="n">cli</span> <span class="o">=</span> <span class="k">new</span> <span class="nc">CliAdapter</span><span class="o">(</span><span class="n">taskService</span><span class="o">);</span>
        <span class="n">cli</span><span class="o">.</span><span class="na">run</span><span class="o">();</span>

        <span class="c1">// For REST, Spring Boot would autowire `taskService` into `RestAdapter`</span>
    <span class="o">}</span>
<span class="o">}</span>
</code></pre></div></div>

<hr />

<h2 id="key-benefits">Key Benefits</h2>

<ol>
  <li><strong>Versatility</strong>: The same <code class="language-plaintext highlighter-rouge">TaskService</code> can serve a CLI, REST API, or even a message consumer without modification.</li>
  <li><strong>Replaceability</strong>: Swap the <code class="language-plaintext highlighter-rouge">InMemoryTaskRepository</code> with a <code class="language-plaintext highlighter-rouge">JdbcTaskRepository</code> without touching the core logic.</li>
  <li><strong>Testability</strong>: The core can be tested with mock ports, no need for real databases or frameworks.</li>
  <li><strong>Future-proofing</strong>: Adding new adapters (e.g., GraphQL, Kafka, Email) requires no change in business logic.</li>
</ol>

<hr />

<h2 id="conclusion">Conclusion</h2>

<p>This simple implementation illustrates the power of Hexagonal Architecture in Java. Even with minimal domain logic, you can see how <strong>ports and adapters provide flexibility and clarity</strong>. The business core is free from infrastructure concerns, making the application more maintainable, extensible, and adaptable to future changes.</p>

<hr />

<h2 id="resources">Resources</h2>

<ol>
  <li><a href="https://alistair.cockburn.us/hexagonal-architecture/">Hexagonal architecture</a>, article by Alistair Cockburn</li>
  <li>Github code <a href="https://github.com/rtaylor02/hexagonal-architecture-simple">here</a></li>
  <li>More sample - Github code <a href="https://github.com/rtaylor02/hexagonal-architecture">here</a> as per article by <a href="https://www.happycoders.eu/software-craftsmanship/hexagonal-architecture-java/">happycoders.eu</a></li>
</ol>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[Hexagonal Architecture, also known as Ports and Adapters, is a software architectural style introduced by Alistair Cockburn. Its goal is to isolate the core business logic from external systems — such as databases, message brokers, or user interfaces — by putting them behind well-defined ports and implementing them through adapters.]]></summary></entry><entry><title type="html">Introduction to Helidon MP: Enterprise Java Microservices</title><link href="http://www.javarchitect.com/helidon-mp-intro/" rel="alternate" type="text/html" title="Introduction to Helidon MP: Enterprise Java Microservices" /><published>2025-09-06T00:00:00+00:00</published><updated>2025-09-06T00:00:00+00:00</updated><id>http://www.javarchitect.com/helidon-mp-intro</id><content type="html" xml:base="http://www.javarchitect.com/helidon-mp-intro/"><![CDATA[<p>In today’s cloud-native world, building lightweight, high-performance microservices in Java often means balancing <strong>standards compliance</strong> with <strong>simplicity and speed</strong>. <strong>Helidon MP</strong>, a project from Oracle, does exactly that: it combines the power of <strong>Eclipse MicroProfile</strong> with a minimalistic runtime, offering a modern platform for enterprise Java microservices.</p>

<p>In this article, we will dive into the world of Helidon MP and create a Helidon MP based project!</p>

<h2 id="what-is-helidon-mp">What Is Helidon MP?</h2>

<p>Helidon MP is the <strong>MicroProfile edition</strong> of Helidon. While Helidon SE provides a functional, low-level API for microservices, Helidon MP adds a full stack of <strong>enterprise-ready features</strong>:</p>

<ul>
  <li>
    <p><strong>JAX-RS</strong> for building RESTful APIs</p>
  </li>
  <li>
    <p><strong>CDI</strong> for dependency injection</p>
  </li>
  <li>
    <p><strong>JSON-P/B</strong> for JSON processing</p>
  </li>
  <li>
    <p><strong>Health checks, metrics, and tracing</strong> for observability</p>
  </li>
  <li>
    <p><strong>Fault tolerance and configuration</strong> via MicroProfile APIs</p>
  </li>
</ul>

<p>Unlike traditional Java EE servers, Helidon MP is <strong>lightweight, fast, and cloud-native</strong>. It doesn’t require a full application server and runs directly on the JVM or as a <strong>GraalVM native image</strong>.</p>

<h2 id="why-choose-helidon-mp">Why Choose Helidon MP?</h2>

<ul>
  <li>
    <p><strong>Standards-Based</strong>: Implementing MicroProfile ensures portability across compliant frameworks.</p>
  </li>
  <li>
    <p><strong>Cloud-Ready</strong>: Out-of-the-box support for <strong>Docker, Kubernetes, Prometheus, and OpenTelemetry</strong>.</p>
  </li>
  <li>
    <p><strong>High Performance</strong>: Minimal overhead and fast startup times make it ideal for microservices and serverless deployments.</p>
  </li>
  <li>
    <p><strong>Modern Java Features</strong>: Supports Java 21 features, including virtual threads, enabling simple, efficient concurrency.</p>
  </li>
</ul>

<h2 id="getting-started">Getting Started</h2>
<h3 id="using-helidon-project-generator">Using Helidon Project Generator</h3>
<p>Head to <a href="https://helidon.io/starter/4.2.6?step=1">helidon’s starter page</a> for a guided starter project generator. 
<img src="../assets/images/posts/2025-09-06-helidon-mp-intro/helidon_io_starter.png" alt="Helidon starter generator" /></p>

<p>Simply click download to access your project.</p>

<h3 id="using-maven">Using Maven</h3>
<p>A minimal Helidon MP project can be created using Maven:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>mvn -U archetype:generate -DinteractiveMode=false \
    -DarchetypeGroupId=io.helidon.archetypes \
    -DarchetypeArtifactId=helidon-quickstart-mp \
    -DarchetypeVersion=4.1.0 \
    -DgroupId=com.javarchitect.helidon \
    -DartifactId=helidon-mp-example \
    -Dpackage=com.javarchitect.helidon
</code></pre></div></div>
<p>From there, you can define JAX-RS endpoints, add MicroProfile health checks, and run your microservice in a few simple steps.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Helidon MP is perfect for developers who want <strong>enterprise Java microservices</strong> that are <strong>lightweight, standards-compliant, and cloud-ready</strong>. By leveraging MicroProfile and Helidon’s high-performance runtime, you get the best of both worlds: modern microservices architecture without the complexity of a traditional Java EE server.</p>

<p>For more information, visit the official <a href="https://helidon.io/?utm_source=chatgpt.com">Helidon website</a>.</p>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[In today’s cloud-native world, building lightweight, high-performance microservices in Java often means balancing standards compliance with simplicity and speed. Helidon MP, a project from Oracle, does exactly that: it combines the power of Eclipse MicroProfile with a minimalistic runtime, offering a modern platform for enterprise Java microservices.]]></summary></entry><entry><title type="html">Java Data Structures Explained: When to Use ArrayList, HashMap, and More</title><link href="http://www.javarchitect.com/java-collections-framework-easy-decision-maker/" rel="alternate" type="text/html" title="Java Data Structures Explained: When to Use ArrayList, HashMap, and More" /><published>2025-09-05T00:00:00+00:00</published><updated>2025-09-05T00:00:00+00:00</updated><id>http://www.javarchitect.com/java-collections-framework-easy-decision-maker</id><content type="html" xml:base="http://www.javarchitect.com/java-collections-framework-easy-decision-maker/"><![CDATA[<p>Choosing the right data structure in Java can make the difference between code that simply works and code that is truly fast, scalable, and reliable. With the vast toolkit offered by the Java Collections Framework and java.util.concurrent, it’s easy to feel overwhelmed — ArrayList or LinkedList? HashMap or ConcurrentHashMap? BlockingQueue or lock-free alternatives?</p>
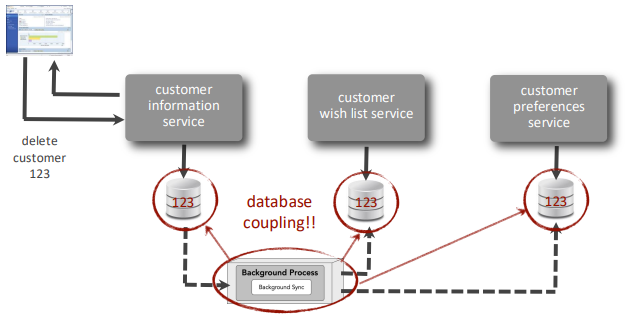
<p>In this article, we’ll cut through the noise with clear, practical guidance: which structure to use, when to use it, and why. From performance considerations to concurrency safety, this guide will help you make the smart choice every time.</p>

<p>Let’s go through the Java Collections Framework (and a few extras in java.util.concurrent), but framed from a practical performance + concurrency perspective.</p>

<h2 id="-core-java-data-structures-and-when-to-use-them">📚 <strong>Core Java Data Structures and When to Use Them</strong></h2>
<h3 id="list-implementations">List Implementations</h3>
<p><strong>ArrayList</strong><br />
✅ Best for: Random access, iteration.<br />
❌ Avoid when: Many insertions/deletions in the middle.<br />
Perf: Backed by an array, so get(int) and set(int) are O(1), but inserts/removes (except at end) are O(n).</p>

<p><strong><em>LinkedList</em></strong><br />
✅ Best for: Frequent inserts/removes at both ends (addFirst, addLast).<br />
❌ Poor for: Random access (get(i) is O(n)).<br />
Perf: Doubly linked nodes, predictable memory usage but slower iteration (cache-unfriendly).</p>

<p><strong>CopyOnWriteArrayList (concurrent)</strong><br />
✅ Best for: Mostly-read, rarely-write scenarios in multithreaded contexts (e.g., event listeners).<br />
Perf: Writes copy the entire array → expensive, but reads are lock-free and very fast.</p>

<h3 id="set-implementations">Set Implementations</h3>
<p><strong>HashSet</strong><br />
✅ Best for: Fast lookup and uniqueness.<br />
Perf: Backed by HashMap, average O(1) add/remove/contains.</p>

<p><strong>LinkedHashSet</strong><br />
✅ Best for: Fast lookup + predictable iteration order (insertion order).<br />
Perf: Slightly slower than HashSet due to linked list overhead.</p>

<p><strong>TreeSet</strong><br />
✅ Best for: Sorted unique data, range queries.<br />
Perf: Backed by a Red-Black tree. All ops are O(log n).</p>

<p><strong>ConcurrentSkipListSet</strong> (concurrent)<br />
✅ Best for: Thread-safe sorted set with lock-free reads.<br />
Perf: Based on skip lists, good scalability under contention.</p>

<h3 id="map-implementations">Map Implementations</h3>
<p><strong>HashMap</strong><br />
✅ Best for: General key/value storage with fast lookup.<br />
Perf: Average O(1) for get/put. Not thread-safe.</p>

<p><strong>LinkedHashMap</strong><br />
✅ Best for: Fast lookup + predictable iteration order.<br />
Special: Supports access-order iteration → ideal for LRU caches.</p>

<p><strong>TreeMap</strong><br />
✅ Best for: Sorted map with range queries.<br />
Perf: O(log n) for get/put. Higher overhead than HashMap.</p>

<p><strong>ConcurrentHashMap</strong> (concurrent)<br />
✅ Best for: High-concurrency map with frequent reads/writes.<br />
Perf: Lock-striping, non-blocking reads, scalable under contention.</p>

<p><strong>WeakHashMap</strong><br />
✅ Best for: Caches where keys should be GC-collected when no longer referenced.<br />
Perf: Slight overhead due to reference queues.</p>

<h3 id="queue--deque-implementations">Queue &amp; Deque Implementations</h3>
<p><strong>ArrayDeque</strong><br />
✅ Best for: Fast stack/queue (double-ended).<br />
Perf: Much faster than LinkedList for stack/queue operations.</p>

<p><strong>PriorityQueue</strong><br />
✅ Best for: Always retrieving the “smallest” or “largest” element.<br />
Perf: Backed by a binary heap, O(log n) insertion/removal.</p>

<p><strong>ConcurrentLinkedQueue</strong> (concurrent)<br />
✅ Best for: Lock-free FIFO in multi-threaded environments.<br />
Perf: Scales well with many producers/consumers.</p>

<p><strong>BlockingQueue</strong> family (e.g., LinkedBlockingQueue, ArrayBlockingQueue)<br />
✅ Best for: Producer/consumer designs with thread blocking.<br />
Perf: Choice depends on bounded/unbounded and fairness requirements.</p>

<p><strong>ConcurrentLinkedDeque</strong> (concurrent)<br />
✅ Best for: Lock-free double-ended queue, suitable for work-stealing.</p>

<h3 id="specialized-collections">Specialized Collections</h3>
<p><strong>EnumSet / EnumMap</strong><br />
✅ Best for: High-performance collections keyed by enums.<br />
Perf: Backed by bit vectors, extremely fast and memory efficient.</p>

<p><strong>IdentityHashMap</strong><br />
✅ Best for: When key identity (==) matters instead of equality (equals()).<br />
Perf: Rare use cases like serialization, object graph traversal.</p>

<h2 id="-rules-of-thumb">🚀 <strong>Rules of Thumb</strong></h2>
<p><strong>High lookup speed?</strong> → HashMap / HashSet.<br />
<strong>Need ordering?</strong> → LinkedHashMap / TreeSet / TreeMap.<br />
<strong>Sorted &amp; concurrent?</strong> → ConcurrentSkipListMap / ConcurrentSkipListSet.<br />
<strong>Producer/consumer threads?</strong> → BlockingQueue.<br />
<strong>Read-heavy, write-rarely?</strong> → CopyOnWriteArrayList / CopyOnWriteArraySet.<br />
<strong>Event-driven caching?</strong> → LinkedHashMap with access-order eviction.<br />
<strong>GC-aware caching?</strong> → WeakHashMap.</p>

<blockquote>
  <p>⚡<strong>Performance tip</strong>:</p>

  <p>In single-threaded contexts, prefer non-concurrent versions — they’re much faster. For concurrency, always start with ConcurrentHashMap or ConcurrentLinkedQueue before rolling your own synchronization.</p>
</blockquote>

<p>Flow chart based on the description above: 
<a href="http://www.javarchitect.com/_posts/images/2025-09-05-java-collections-framework-easy-decision-maker/05-09-2025-java-collections-mermaid-chart.png"><img src="http://www.javarchitect.com/_posts/images/2025-09-05-java-collections-framework-easy-decision-maker/05-09-2025-java-collections-mermaid-chart.png" alt="Java Collections Framework decision flow chart" title="Decision flow for Java Collections Framework" /></a></p>

<p><strong>Sample code</strong>: <a href="#">Github repo</a><br />
<strong>Mermaid chart code</strong>: <a href="./05-09-2025-java-collections-mermaid-chart.md">here</a></p>]]></content><author><name>Rodney Taylor</name></author><summary type="html"><![CDATA[Choosing the right data structure in Java can make the difference between code that simply works and code that is truly fast, scalable, and reliable. With the vast toolkit offered by the Java Collections Framework and java.util.concurrent, it’s easy to feel overwhelmed — ArrayList or LinkedList? HashMap or ConcurrentHashMap? BlockingQueue or lock-free alternatives?]]></summary></entry></feed>